


النشر بنقرة واحدة
انطلق فورًا. تتولى Atoms الاستضافة وSSL وإعدادات الخادم حتى تتمكن من التركيز على البناء.
Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context.
لا حاجة إلى بطاقة ائتمانانشر خلال ثوانٍملكية كاملة للكود
موثوق من قبل عملاء من


GLM-5.2 is an AI model available through Atoms for coding, reasoning, research, and tool-driven workflows. Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context. Review the model details below, compare alternatives, and start with the example prompt in the hero.
| Decision point | What to check |
|---|---|
| Best for | coding, reasoning, research, and tool-driven workflows |
| Access | Available through the Atoms model workflow when shown in the current model selector |
| Evidence | Provider information and the practical guidance on this page |
| Limitation | Results depend on the prompt, task, selected settings, and review workflow |
| Page verified | August 23, 2026 |
GLM-5.2 is Z.ai’s flagship foundation model for long-horizon tasks. Z.ai positions it for project-scale engineering contexts where the model must retain architecture, API contracts, repository conventions, and earlier decisions while taking work from requirements to a deployable product. It accepts text input and produces text output.
Z.ai highlights GLM-5.2 for codebase audits, large refactors, API migrations, mobile debugging, Mini Program development, research reproduction, and other workflows where context continuity and reliable follow-through matter.
In August 2026, an anonymous model called Ox Alpha appeared on OpenRouter with a one-week free-access promotion. Developers and Reddit users spent several days trying to identify its provider. Bloomberg later reported that Z.AI confirmed Ox Alpha was a new iteration of its GLM series and planned to release the weights.
The episode matters because it was not only a launch stunt. Early developer reports focused on coding and agent tasks, while the model's identity was investigated through serving behavior, tokenizer and output fingerprints, and error-message similarities. Those community tests are evidence of the investigation—not a substitute for an official model card or a controlled benchmark.
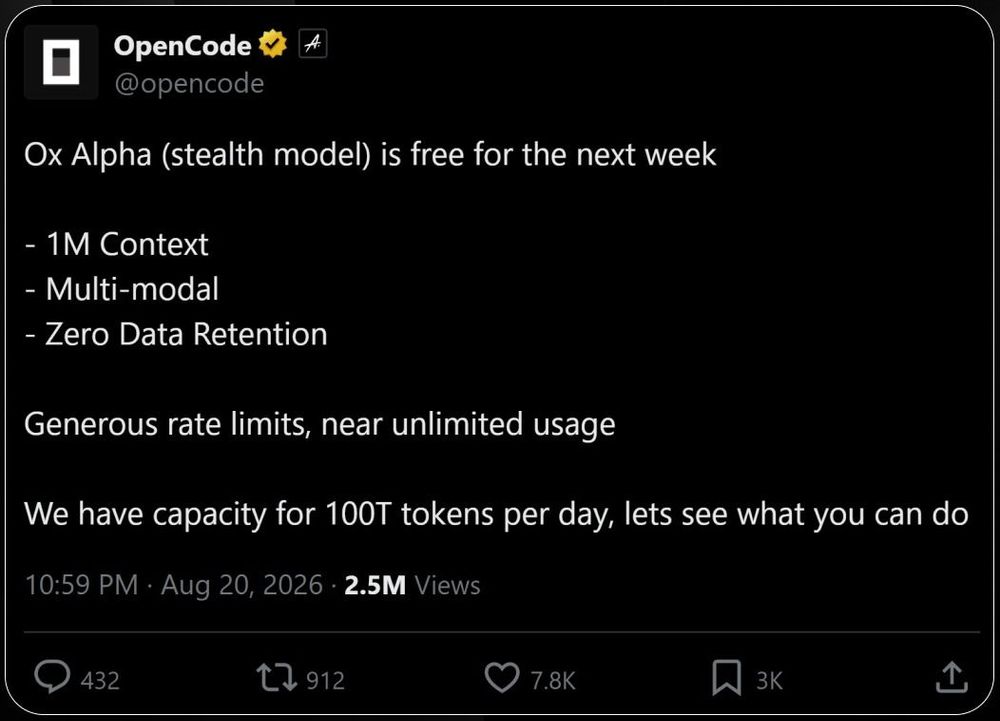
OpenCode's Ox Alpha announcement, cropped to remove unrelated publisher branding. This image documents a social-media claim, not independent verification.
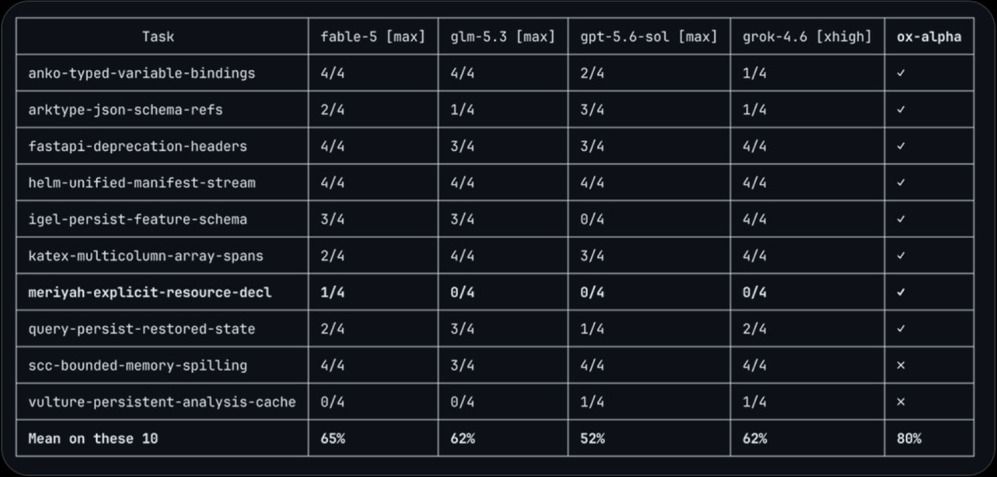
Community-shared DeepSWE subset comparison. The image itself notes that the sample is only ten tasks; it should not be generalized to overall model quality.
For builders, the right takeaway is not “Ox Alpha beats every model.” It is that Z.AI demonstrated a high-attention path from anonymous preview to confirmed GLM release, while the strongest early user signal appeared in coding workflows. Test the exact model, harness, prompt, context, retries, and accepted changes before making a production decision.
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
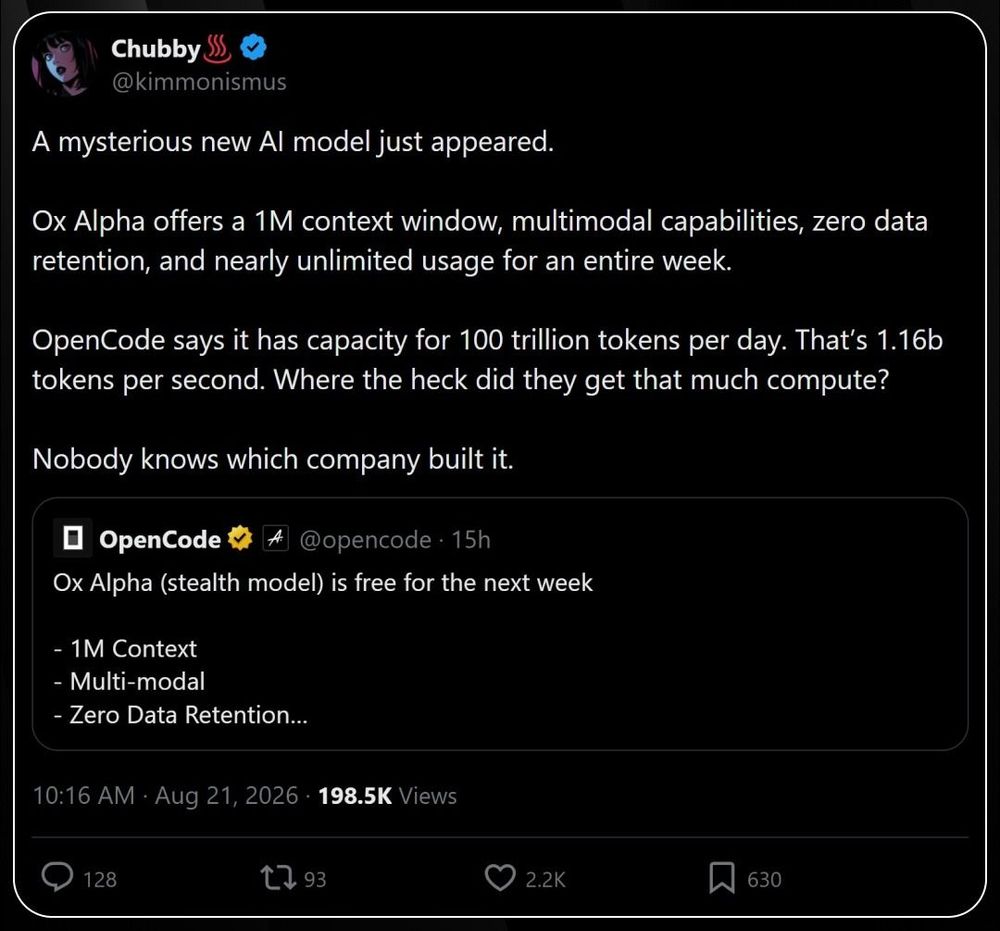
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
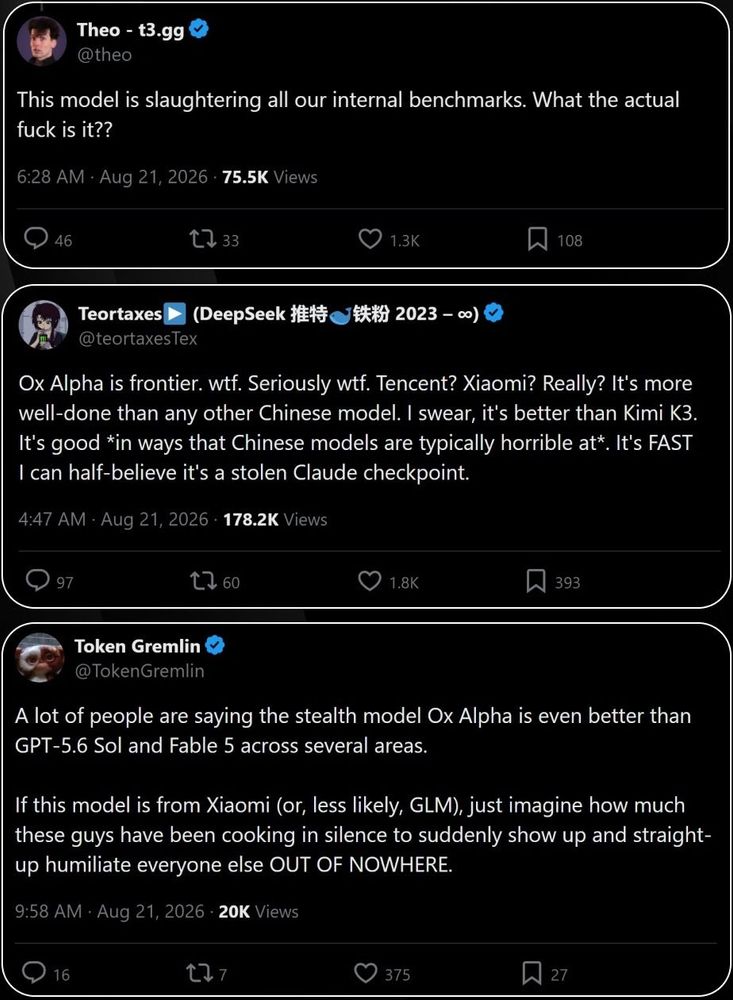
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
 لماذا Atoms
فريق ذكاء اصطناعي متعدد الوكلاء
يعمل مدير المنتج والمهندس والمصمم معًا لتحويل مطالبتك إلى منتج متكامل.
أطلق خلال دقائق، لا أشهر
انتقل من الفكرة إلى منتج منشور عبر محادثة واحدة. دون إعداد أو تهيئة.
ملكية كاملة للكود
صدّر إلى GitHub في أي وقت. كل شيء تملكه أنت — دون احتجاز من المورّد.
انطلق فورًا. تتولى Atoms الاستضافة وSSL وإعدادات الخادم حتى تتمكن من التركيز على البناء.

حرّر تطبيقك بصريًا — عدّل التخطيطات والألوان والمحتوى دون لمس الكود.

أضف ميزات مدعومة بالذكاء الاصطناعي — روبوتات الدردشة، وتوليد الصور، وتحليل النصوص — باستخدام مطالبة واحدة.

يتعاون فريق ذكاء اصطناعي متكامل — مدير منتج ومهندس ومصمم — لتحويل مطالبتك إلى منتج يعمل.
لوحة تحكم SaaS
أنشئ منصة SaaS متكاملة تتضمن مصادقة المستخدمين والفوترة والتحليلات في الوقت الفعلي.
متجر التجارة الإلكترونية
أنشئ كتالوج منتجات مع سلة تسوق وإتمام الشراء ومدفوعات Stripe.
أدوات داخلية
أنشئ واطلق لوحات الإدارة وأنظمة CRM وأدوات سير العمل لفريقك خلال دقائق.
تطبيق الجوال
أنشئ تطبيقات جوال متعددة المنصات بواجهة تبدو أصلية وإشعارات فورية.
تطبيقات وصفحات حقيقية أطلقتها الفرق على Atoms — اختر واحدًا كنقطة بداية.
صف ممارستك القانونية واحصل على موقع منشور لمكتب المحاماة يتضمن مجالات الممارسة وملفات المحامين وحجز الاستشارات.
احصل على موقع وكالة منشور يتضمن صفحات معرض الأعمال، ودراسات الحالة، وملفات الفريق، والتقاط العملاء المحتملين.
حوّل أفكار المنتجات الخام إلى نماذج أولية تفاعلية يمكنك النقر عليها ومشاركتها واختبارها في دقائق.
قم بوصف المنتج الذي تريده، ستقوم Atoms ببناء التطبيق والموقع لك.
اعرض أعمالك على موقع ملف أعمال منشور يضم صفحات مشاريع ومعارض وشهادات ونماذج تواصل.
حوّل منتجاتك إلى متجر إلكتروني بسيط ومركّز دون لمس القوالب أو المكونات الإضافية أو الشيفرات.
Atomsلا حاجة إلى بطاقة ائتمان. ولا إلى إعداد. فقط صف ما تريده وسيتولى Atoms إنجازه.
Turn project-scale coding and long-horizon agent ideas into products you can review, verify, and deploy.
