


Implementatie met één klik
Ga direct live. Atoms regelt hosting, SSL en serverconfiguratie zodat jij je kunt richten op bouwen.
Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context.
Geen creditcard vereistImplementeer in secondenVolledig code-eigendom
Vertrouwd door klanten uit


GLM-5.2 is an AI model available through Atoms for coding, reasoning, research, and tool-driven workflows. Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context. Review the model details below, compare alternatives, and start with the example prompt in the hero.
| Decision point | What to check |
|---|---|
| Best for | coding, reasoning, research, and tool-driven workflows |
| Access | Available through the Atoms model workflow when shown in the current model selector |
| Evidence | Provider information and the practical guidance on this page |
| Limitation | Results depend on the prompt, task, selected settings, and review workflow |
| Page verified | August 23, 2026 |
GLM-5.2 is Z.ai’s flagship foundation model for long-horizon tasks. Z.ai positions it for project-scale engineering contexts where the model must retain architecture, API contracts, repository conventions, and earlier decisions while taking work from requirements to a deployable product. It accepts text input and produces text output.
Z.ai highlights GLM-5.2 for codebase audits, large refactors, API migrations, mobile debugging, Mini Program development, research reproduction, and other workflows where context continuity and reliable follow-through matter.
In August 2026, an anonymous model called Ox Alpha appeared on OpenRouter with a one-week free-access promotion. Developers and Reddit users spent several days trying to identify its provider. Bloomberg later reported that Z.AI confirmed Ox Alpha was a new iteration of its GLM series and planned to release the weights.
The episode matters because it was not only a launch stunt. Early developer reports focused on coding and agent tasks, while the model's identity was investigated through serving behavior, tokenizer and output fingerprints, and error-message similarities. Those community tests are evidence of the investigation—not a substitute for an official model card or a controlled benchmark.
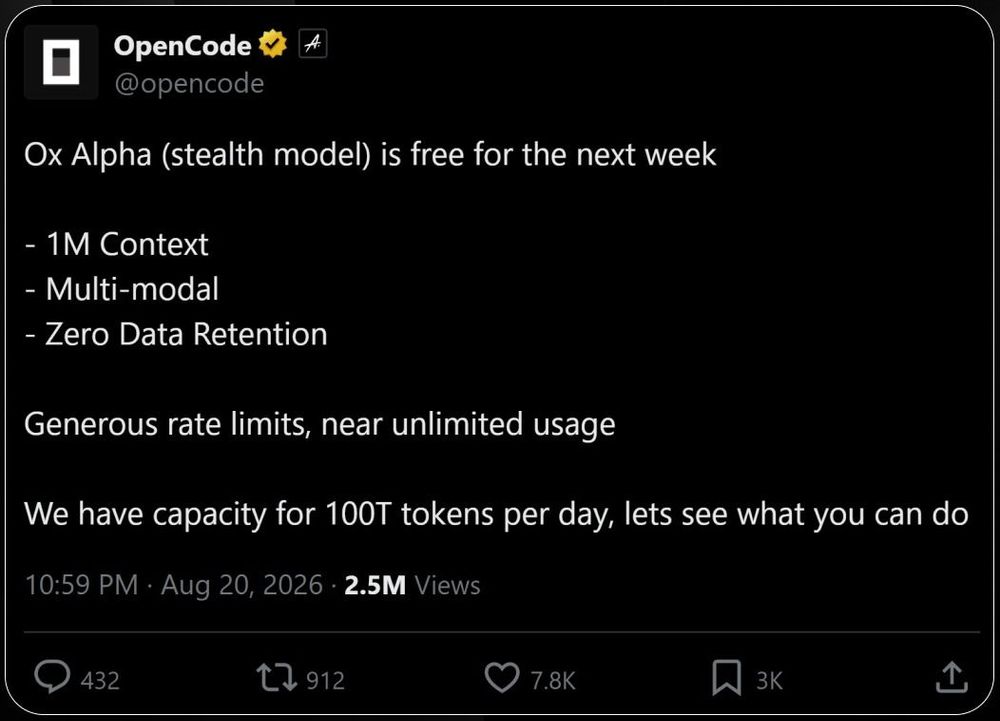
OpenCode's Ox Alpha announcement, cropped to remove unrelated publisher branding. This image documents a social-media claim, not independent verification.
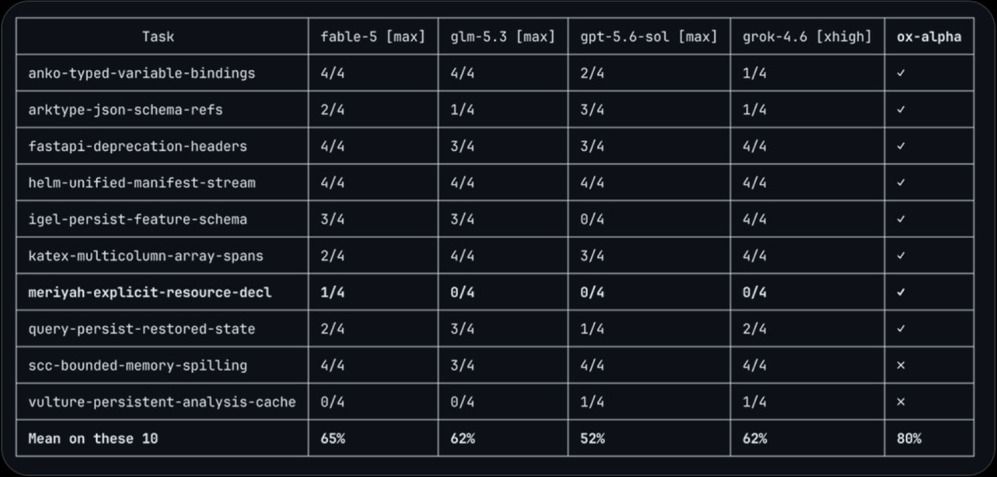
Community-shared DeepSWE subset comparison. The image itself notes that the sample is only ten tasks; it should not be generalized to overall model quality.
For builders, the right takeaway is not “Ox Alpha beats every model.” It is that Z.AI demonstrated a high-attention path from anonymous preview to confirmed GLM release, while the strongest early user signal appeared in coding workflows. Test the exact model, harness, prompt, context, retries, and accepted changes before making a production decision.
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
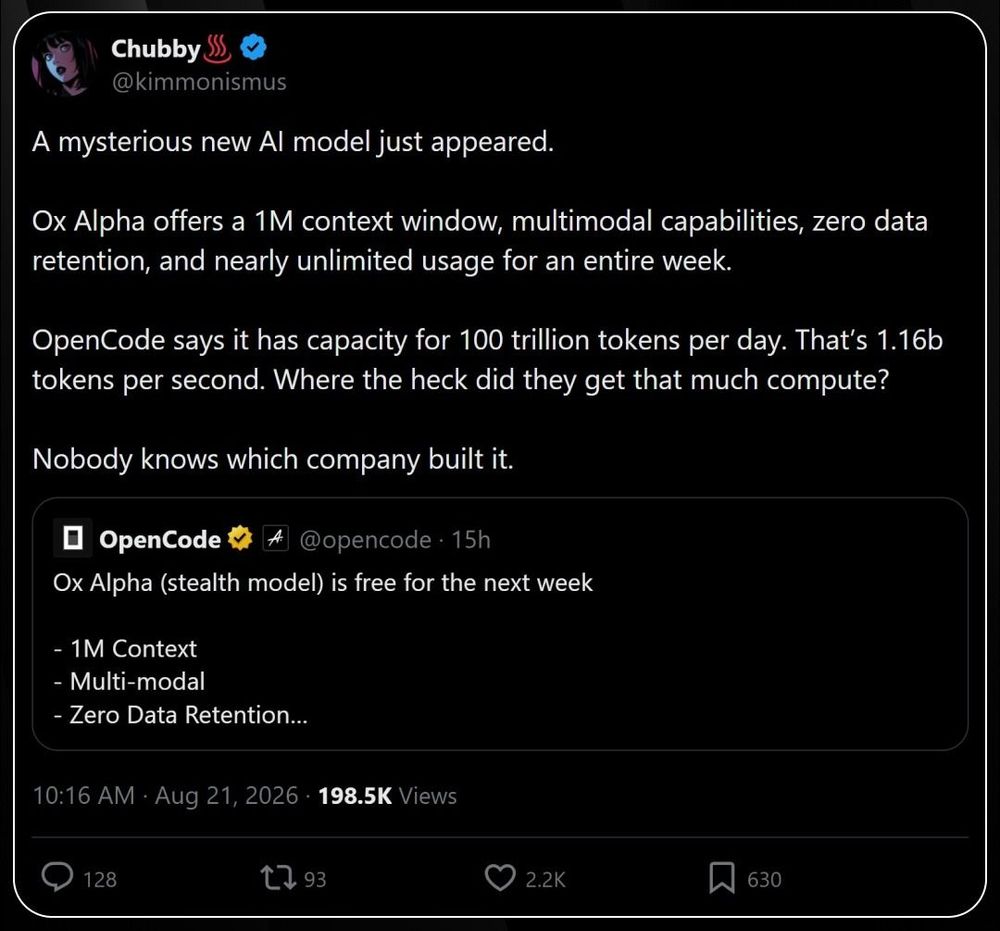
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
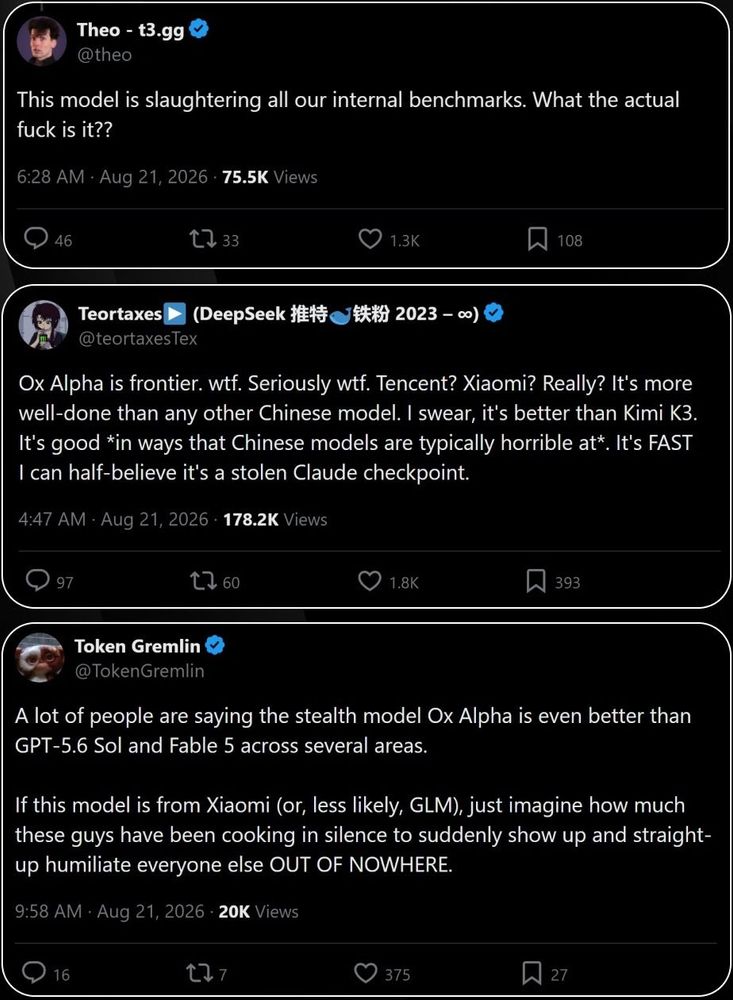
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
 Waarom Atoms
Multi-agent AI-team
PM, engineer en designer werken samen om je prompt om te zetten in een compleet product.
Lever in minuten, niet in maanden
Ga van idee naar gedeployed product met één gesprek. Geen setup, geen configuratie.
Volledig code-eigendom
Exporteer op elk moment naar GitHub. Alles is van jou — geen leverancierslock-in.
Ga direct live. Atoms regelt hosting, SSL en serverconfiguratie zodat jij je kunt richten op bouwen.

Bewerk je app visueel — pas layouts, kleuren en content aan zonder code aan te raken.

Voeg AI-functies toe — chatbots, beeldgeneratie, tekstanalyse — met één enkele prompt.

Een volledig AI-team — PM, engineer en designer — werkt samen om je prompt om te zetten in een werkend product.
SaaS-dashboard
Bouw een full-stack SaaS met gebruikersauthenticatie, facturering en realtime analyses.
E-commercewinkel
Maak een productcatalogus met winkelwagen, checkout en Stripe-betalingen.
Interne tools
Lever in enkele minuten adminpanelen, CRM's en workflowtools voor je team op.
Mobiele app
Bouw cross-platform mobiele apps met een native aanvoelende UI en pushmeldingen.
Echte apps en pagina's die teams op Atoms hebben uitgebracht — kies er één als startpunt.
Beschrijf uw praktijk en ontvang een live website voor uw advocatenkantoor met praktijkgebieden, advocatenprofielen en consultboeking.
Krijg een live bureausite met portfoliopagina's, case studies, teamprofielen en leadgeneratie.
Zet ruwe productideeën om in interactieve prototypes die je in enkele minuten kunt klikken, delen en testen.
Beschrijf het product dat je wilt, Atoms bouwt de app en website voor jou.
Presenteer je werk op een live portfoliosite met projectpagina's, galerijen, testimonials en contactformulieren.
Onderzoek markten, beoordeel haalbaarheid en bouw een MVP vanuit één prompt in natuurlijke taal.
AtomsGeen creditcard. Geen setup. Beschrijf gewoon wat je wilt en Atoms levert het.
Turn project-scale coding and long-horizon agent ideas into products you can review, verify, and deploy.
