


Deploy com um clique
Publique instantaneamente. O Atoms cuida da hospedagem, SSL e configuração do servidor para que você possa focar em construir.
Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context.
Não é necessário cartão de créditoFaça o deploy em segundosPropriedade total do código
Confiado por clientes de


GLM-5.2 is an AI model available through Atoms for coding, reasoning, research, and tool-driven workflows. Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context. Review the model details below, compare alternatives, and start with the example prompt in the hero.
| Decision point | What to check |
|---|---|
| Best for | coding, reasoning, research, and tool-driven workflows |
| Access | Available through the Atoms model workflow when shown in the current model selector |
| Evidence | Provider information and the practical guidance on this page |
| Limitation | Results depend on the prompt, task, selected settings, and review workflow |
| Page verified | August 23, 2026 |
GLM-5.2 is Z.ai’s flagship foundation model for long-horizon tasks. Z.ai positions it for project-scale engineering contexts where the model must retain architecture, API contracts, repository conventions, and earlier decisions while taking work from requirements to a deployable product. It accepts text input and produces text output.
Z.ai highlights GLM-5.2 for codebase audits, large refactors, API migrations, mobile debugging, Mini Program development, research reproduction, and other workflows where context continuity and reliable follow-through matter.
In August 2026, an anonymous model called Ox Alpha appeared on OpenRouter with a one-week free-access promotion. Developers and Reddit users spent several days trying to identify its provider. Bloomberg later reported that Z.AI confirmed Ox Alpha was a new iteration of its GLM series and planned to release the weights.
The episode matters because it was not only a launch stunt. Early developer reports focused on coding and agent tasks, while the model's identity was investigated through serving behavior, tokenizer and output fingerprints, and error-message similarities. Those community tests are evidence of the investigation—not a substitute for an official model card or a controlled benchmark.
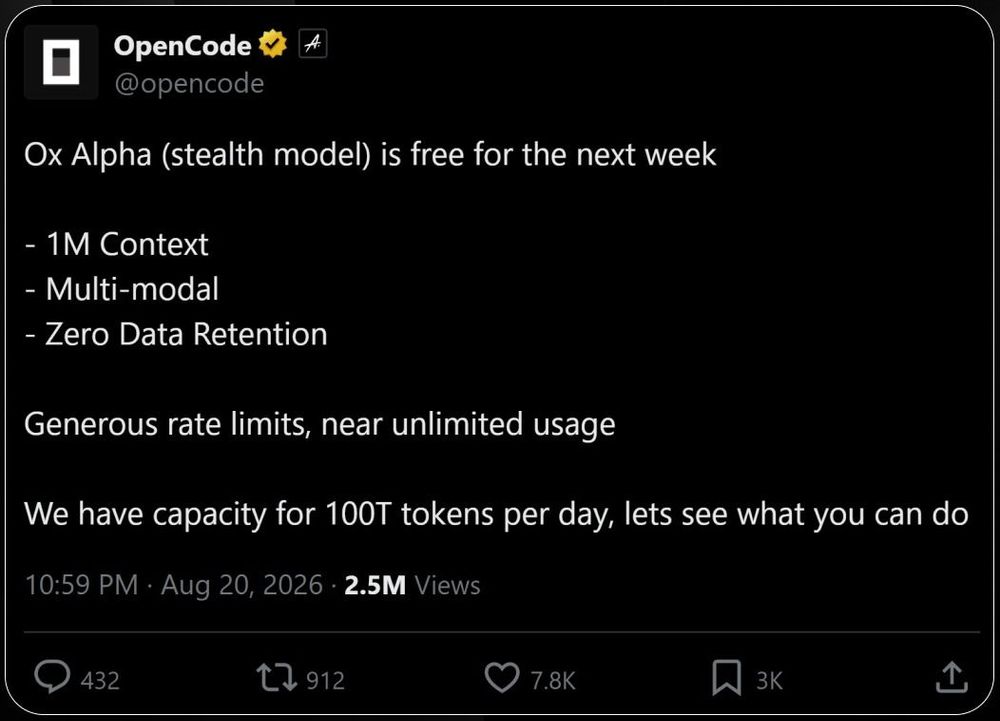
OpenCode's Ox Alpha announcement, cropped to remove unrelated publisher branding. This image documents a social-media claim, not independent verification.
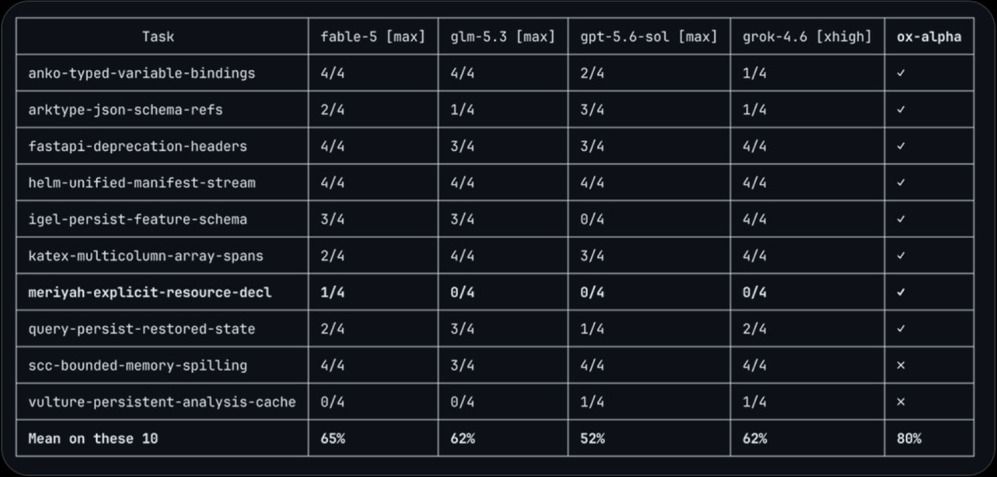
Community-shared DeepSWE subset comparison. The image itself notes that the sample is only ten tasks; it should not be generalized to overall model quality.
For builders, the right takeaway is not “Ox Alpha beats every model.” It is that Z.AI demonstrated a high-attention path from anonymous preview to confirmed GLM release, while the strongest early user signal appeared in coding workflows. Test the exact model, harness, prompt, context, retries, and accepted changes before making a production decision.
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
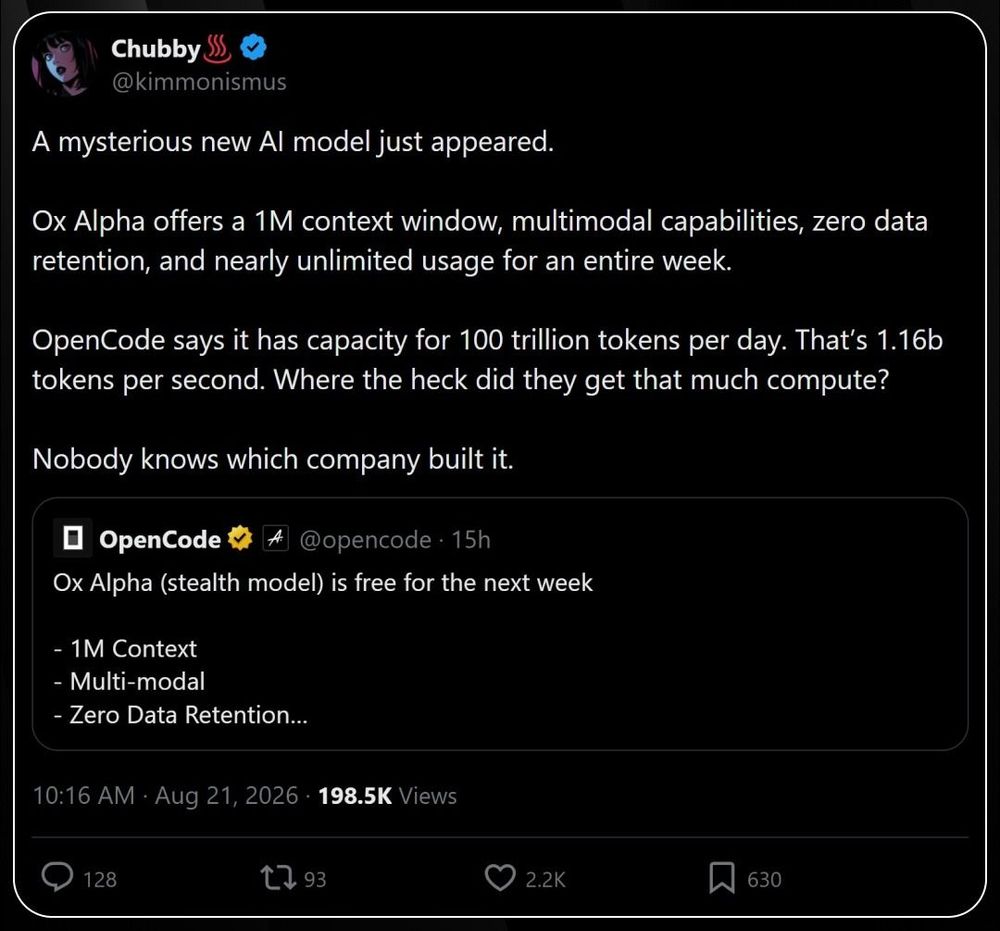
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
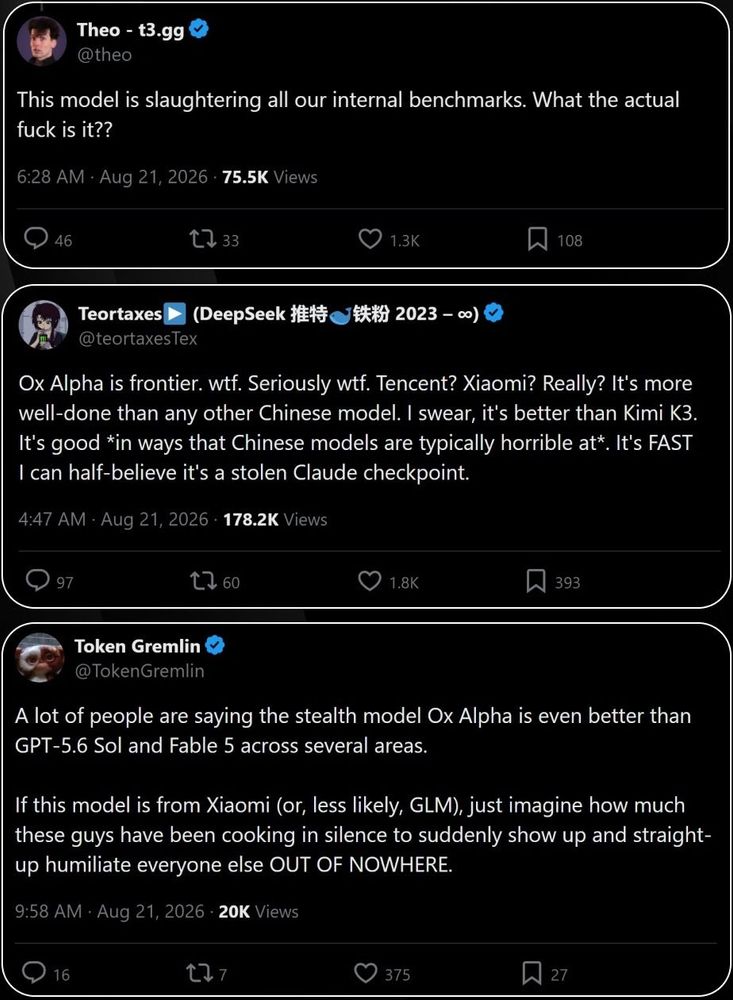
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
 Por que Atoms
Equipe de IA multiagente
PM, engenheiro e designer trabalham juntos para transformar seu prompt em um produto completo.
Lance em minutos, não em meses
Vá da ideia ao produto implantado com uma única conversa. Sem setup, sem configuração.
Propriedade total do código
Exporte para o GitHub a qualquer momento. Tudo é seu — sem vendor lock-in.
Publique instantaneamente. O Atoms cuida da hospedagem, SSL e configuração do servidor para que você possa focar em construir.

Edite seu app visualmente — ajuste layouts, cores e conteúdo sem tocar no código.

Adicione recursos com IA — chatbots, geração de imagens, análise de texto — com um único prompt.

Uma equipe completa de IA — PM, Engineer, Designer — colabora para transformar seu prompt em um produto funcional.
Dashboard SaaS
Crie um SaaS full-stack com autenticação de usuários, cobrança e análises em tempo real.
Loja de e-commerce
Crie um catálogo de produtos com carrinho, checkout e pagamentos via Stripe.
Ferramentas internas
Lance painéis administrativos, CRMs e ferramentas de fluxo de trabalho para sua equipe em minutos.
Aplicativo móvel
Crie aplicativos móveis multiplataforma com UI com sensação nativa e notificações push.
Apps e páginas reais que equipes já lançaram no Atoms — escolha uma como ponto de partida.
Descreva sua atuação e receba um site de escritório de advocacia publicado, com áreas de atuação, perfis de advogados e agendamento de consultas.
Tenha um site de agência publicado com páginas de portfólio, estudos de caso, perfis da equipe e captação de leads.
Transforme ideias iniciais de produtos em protótipos interativos que você pode clicar, compartilhar e testar em minutos.
Descreva o produto que você quer; a Atoms cria o aplicativo e o site para você.
Mostre seu trabalho em um site de portfólio publicado com páginas de projetos, galerias, depoimentos e formulários de contato.
Pesquise mercados, avalie a viabilidade e crie um MVP a partir de um único prompt em linguagem natural.
AtomsSem cartão de crédito. Sem configuração. Basta descrever o que você quer e o Atoms entrega.
Turn project-scale coding and long-horizon agent ideas into products you can review, verify, and deploy.
