


Despliegue con un clic
Publica al instante. Atoms se encarga del hosting, SSL y la configuración del servidor para que puedas centrarte en crear.
Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context.
No se requiere tarjeta de créditoImplementa en segundosPropiedad total del código
Confiado por clientes de


GLM-5.2 is an AI model available through Atoms for coding, reasoning, research, and tool-driven workflows. Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context. Review the model details below, compare alternatives, and start with the example prompt in the hero.
| Decision point | What to check |
|---|---|
| Best for | coding, reasoning, research, and tool-driven workflows |
| Access | Available through the Atoms model workflow when shown in the current model selector |
| Evidence | Provider information and the practical guidance on this page |
| Limitation | Results depend on the prompt, task, selected settings, and review workflow |
| Page verified | August 23, 2026 |
GLM-5.2 is Z.ai’s flagship foundation model for long-horizon tasks. Z.ai positions it for project-scale engineering contexts where the model must retain architecture, API contracts, repository conventions, and earlier decisions while taking work from requirements to a deployable product. It accepts text input and produces text output.
Z.ai highlights GLM-5.2 for codebase audits, large refactors, API migrations, mobile debugging, Mini Program development, research reproduction, and other workflows where context continuity and reliable follow-through matter.
In August 2026, an anonymous model called Ox Alpha appeared on OpenRouter with a one-week free-access promotion. Developers and Reddit users spent several days trying to identify its provider. Bloomberg later reported that Z.AI confirmed Ox Alpha was a new iteration of its GLM series and planned to release the weights.
The episode matters because it was not only a launch stunt. Early developer reports focused on coding and agent tasks, while the model's identity was investigated through serving behavior, tokenizer and output fingerprints, and error-message similarities. Those community tests are evidence of the investigation—not a substitute for an official model card or a controlled benchmark.
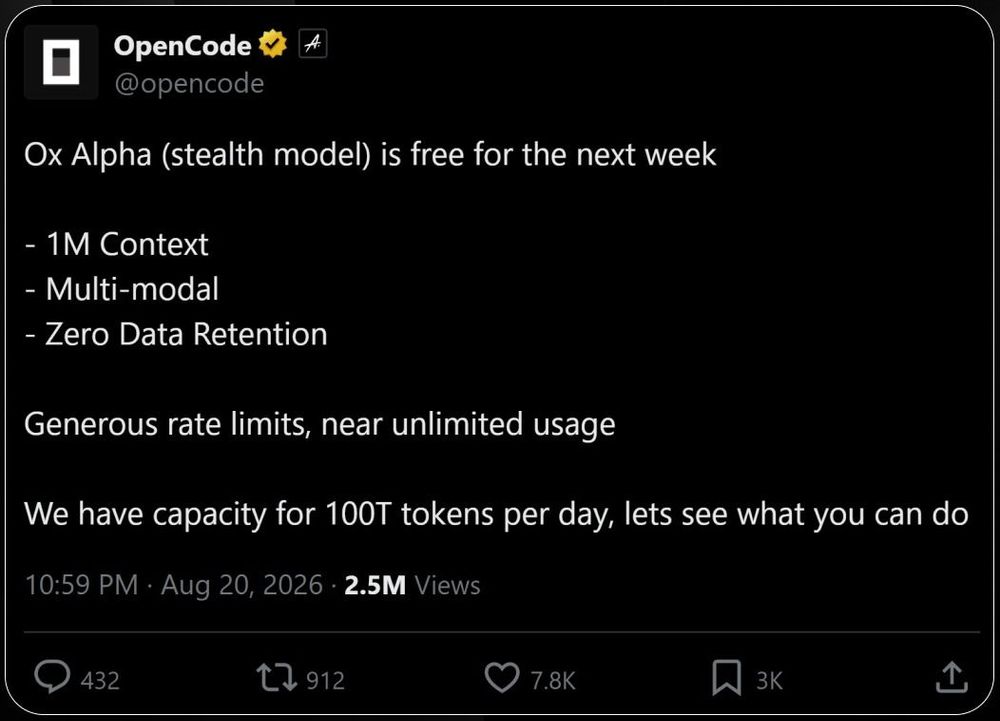
OpenCode's Ox Alpha announcement, cropped to remove unrelated publisher branding. This image documents a social-media claim, not independent verification.
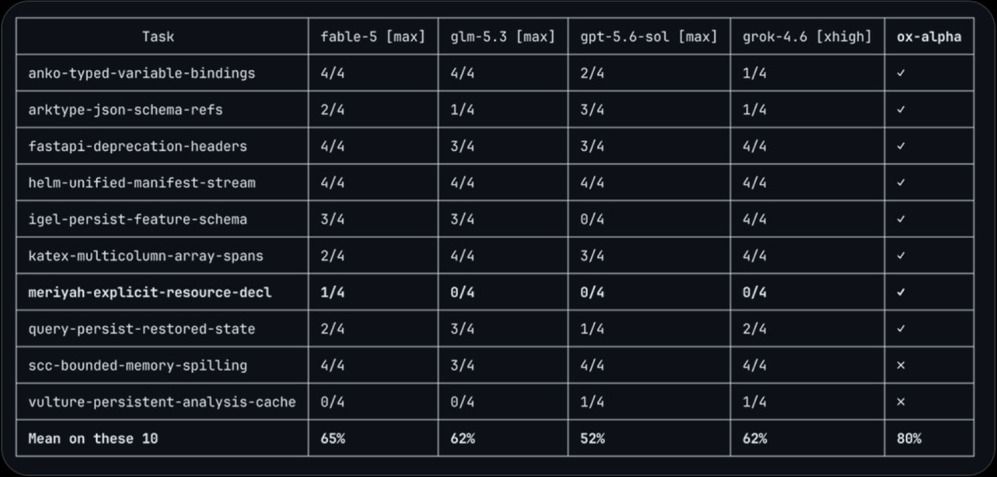
Community-shared DeepSWE subset comparison. The image itself notes that the sample is only ten tasks; it should not be generalized to overall model quality.
For builders, the right takeaway is not “Ox Alpha beats every model.” It is that Z.AI demonstrated a high-attention path from anonymous preview to confirmed GLM release, while the strongest early user signal appeared in coding workflows. Test the exact model, harness, prompt, context, retries, and accepted changes before making a production decision.
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
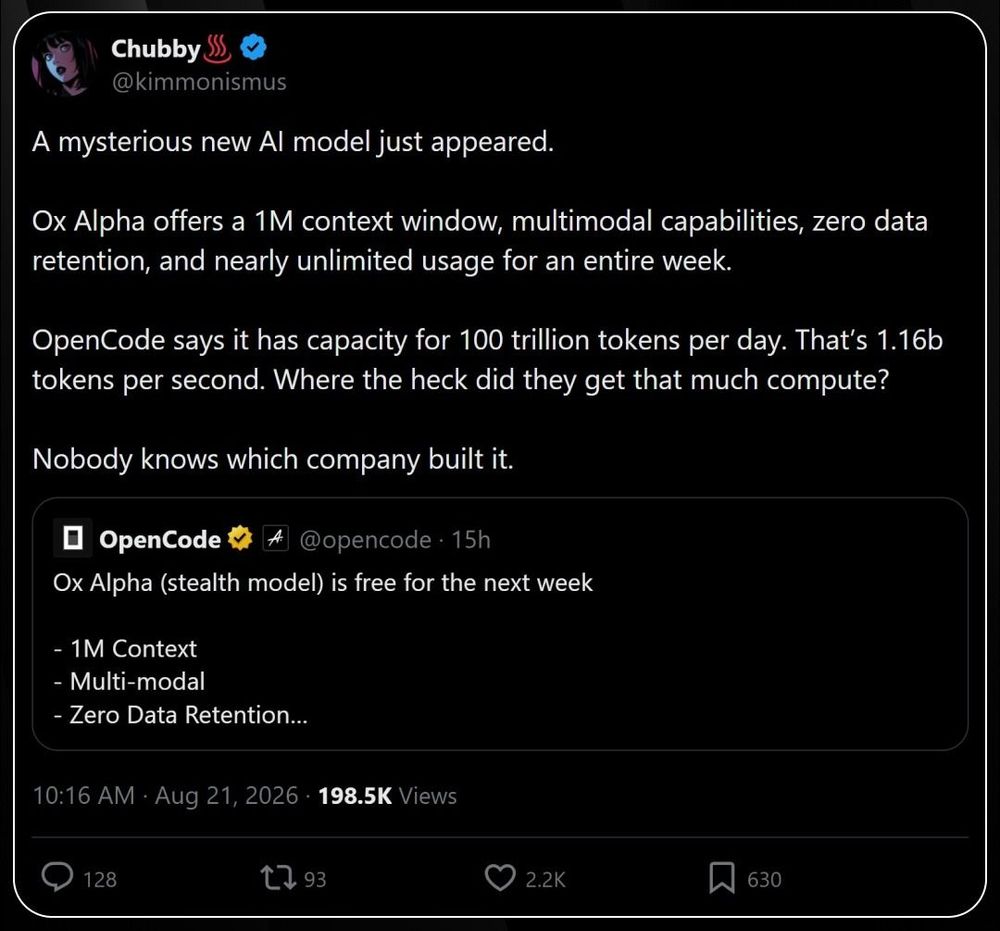
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
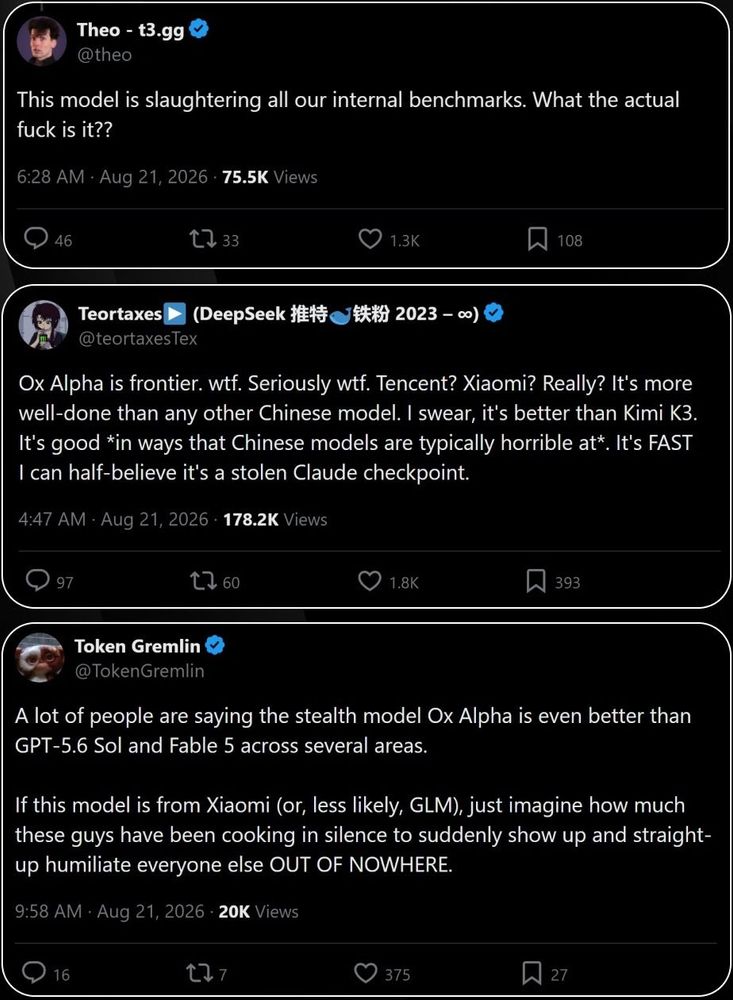
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
 Por qué Atoms
Equipo de IA multiagente
PM, ingeniero y diseñador trabajan juntos para convertir tu prompt en un producto completo.
Lanza en minutos, no en meses
Pasa de la idea al producto desplegado con una sola conversación. Sin instalación ni configuración.
Propiedad total del código
Exporta a GitHub en cualquier momento. Todo te pertenece; sin dependencia del proveedor.
Publica al instante. Atoms se encarga del hosting, SSL y la configuración del servidor para que puedas centrarte en crear.

Edita tu app visualmente: ajusta diseños, colores y contenido sin tocar el código.

Añade funciones impulsadas por IA — chatbots, generación de imágenes, análisis de texto — con un solo prompt.

Un equipo completo de IA — PM, ingeniero y diseñador — colabora para convertir tu prompt en un producto funcional.
Panel de SaaS
Crea un SaaS full-stack con autenticación de usuarios, facturación y analítica en tiempo real.
Tienda de comercio electrónico
Crea un catálogo de productos con carrito, pago y pagos con Stripe.
Herramientas internas
Lanza paneles de administración, CRM y herramientas de flujo de trabajo para tu equipo en minutos.
Aplicación móvil
Crea aplicaciones móviles multiplataforma con una interfaz que se sienta nativa y notificaciones push.
Aplicaciones y páginas reales que los equipos han lanzado en Atoms: elige una como punto de partida.
Describe tu práctica y obtén un sitio web para tu bufete ya desplegado con áreas de práctica, perfiles de abogados y reserva de consultas.
Obtén un sitio de agencia desplegado con páginas de portafolio, casos de estudio, perfiles del equipo y captura de leads.
Convierte ideas de productos en prototipos interactivos que puedes hacer clic, compartir y probar en minutos.
Describe el producto que deseas, Atoms construye la aplicación y el sitio web para ti.
Todo lo que necesitas para lanzar y escalar tu producto de software hoy.
Muestra tu trabajo en un sitio de portafolio desplegado con páginas de proyecto, galerías, testimonios y formularios de contacto.
AtomsSin tarjeta de crédito. Sin configuración. Solo describe lo que quieres y Atoms lo entrega.
Turn project-scale coding and long-horizon agent ideas into products you can review, verify, and deploy.
