دیپلوی با یک کلیک
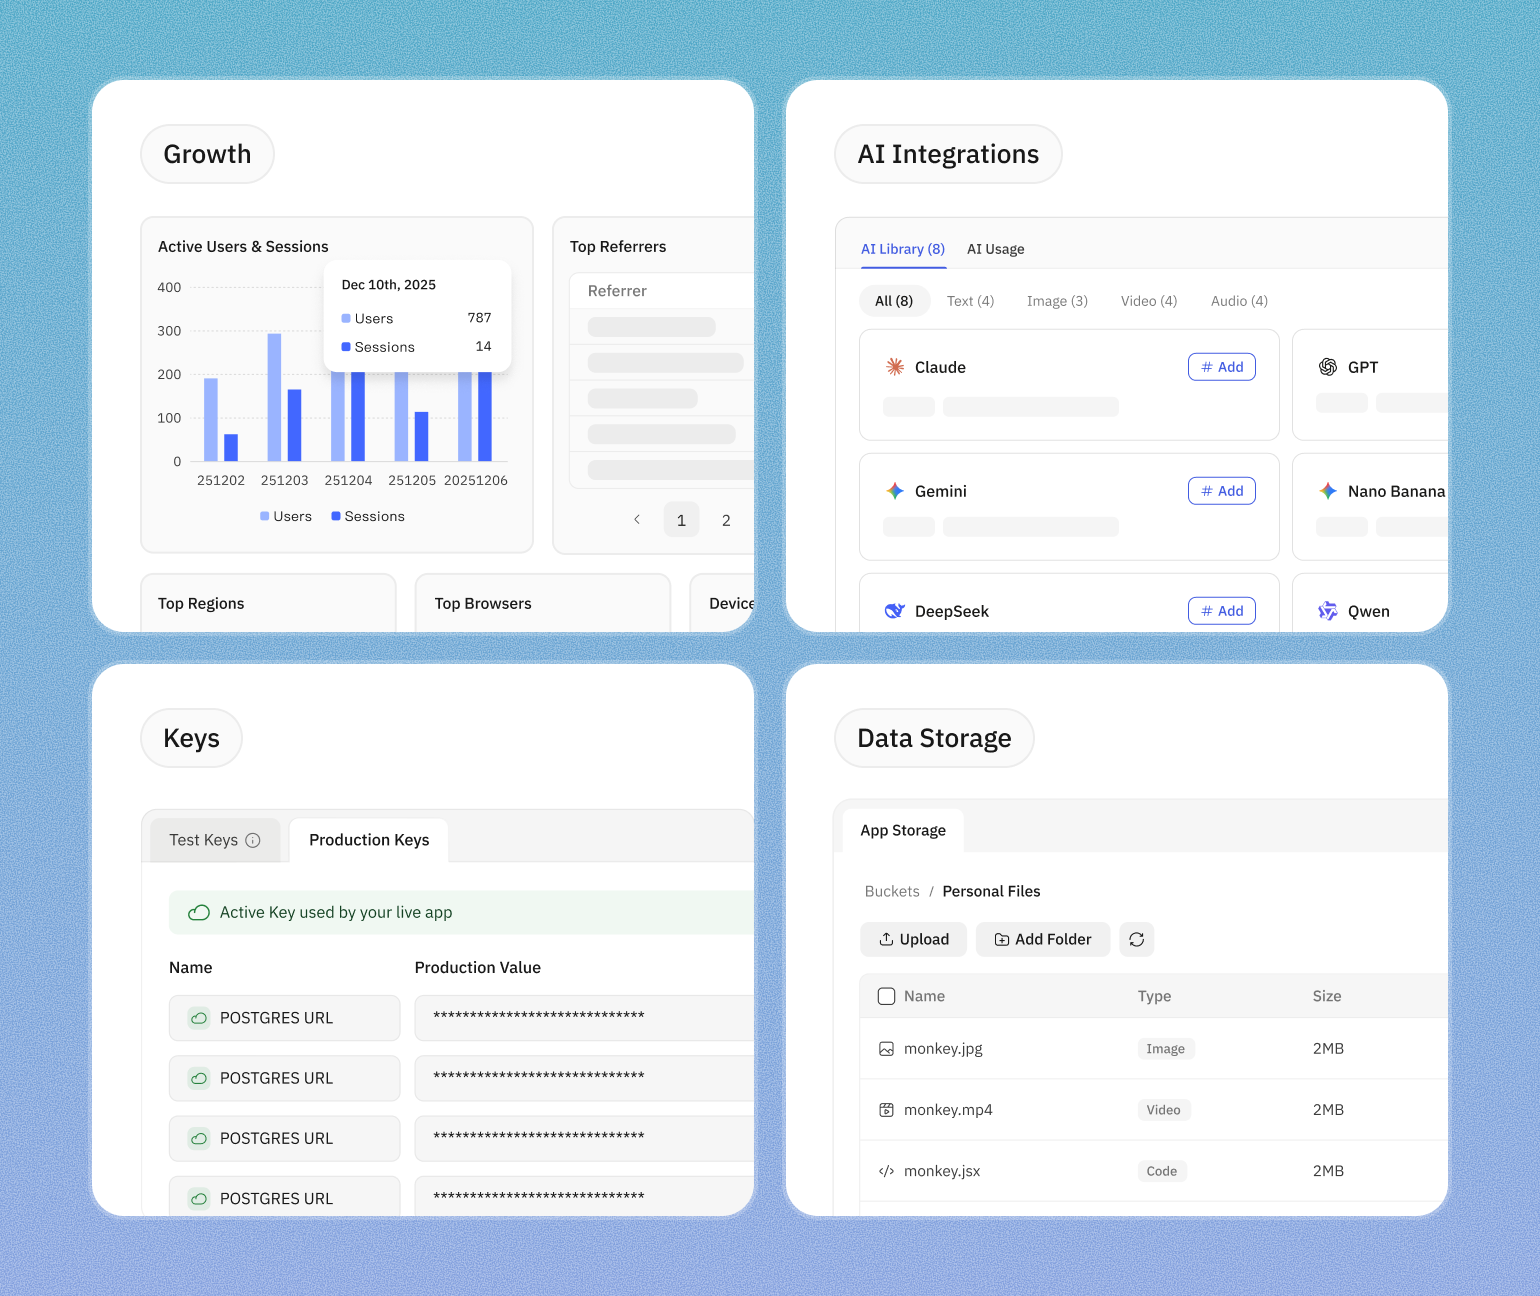
فوراً آنلاین شوید. Atoms میزبانی، SSL و پیکربندی سرور را مدیریت میکند تا شما روی ساخت تمرکز کنید.
Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context.
نیازی به کارت اعتباری نیستدر چند ثانیه دیپلوی کنیدمالکیت کامل کد
مورد اعتماد مشتریانی از
GLM-5.2 is an AI model available through Atoms for coding, reasoning, research, and tool-driven workflows. Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context. Review the model details below, compare alternatives, and start with the example prompt in the hero.
| Decision point | What to check |
|---|---|
| Best for | coding, reasoning, research, and tool-driven workflows |
| Access | Available through the Atoms model workflow when shown in the current model selector |
| Evidence | Provider information and the practical guidance on this page |
| Limitation | Results depend on the prompt, task, selected settings, and review workflow |
| Page verified | August 23, 2026 |
GLM-5.2 is Z.ai’s flagship foundation model for long-horizon tasks. Z.ai positions it for project-scale engineering contexts where the model must retain architecture, API contracts, repository conventions, and earlier decisions while taking work from requirements to a deployable product. It accepts text input and produces text output.
Z.ai highlights GLM-5.2 for codebase audits, large refactors, API migrations, mobile debugging, Mini Program development, research reproduction, and other workflows where context continuity and reliable follow-through matter.
In August 2026, an anonymous model called Ox Alpha appeared on OpenRouter with a one-week free-access promotion. Developers and Reddit users spent several days trying to identify its provider. Bloomberg later reported that Z.AI confirmed Ox Alpha was a new iteration of its GLM series and planned to release the weights.
The episode matters because it was not only a launch stunt. Early developer reports focused on coding and agent tasks, while the model's identity was investigated through serving behavior, tokenizer and output fingerprints, and error-message similarities. Those community tests are evidence of the investigation—not a substitute for an official model card or a controlled benchmark.
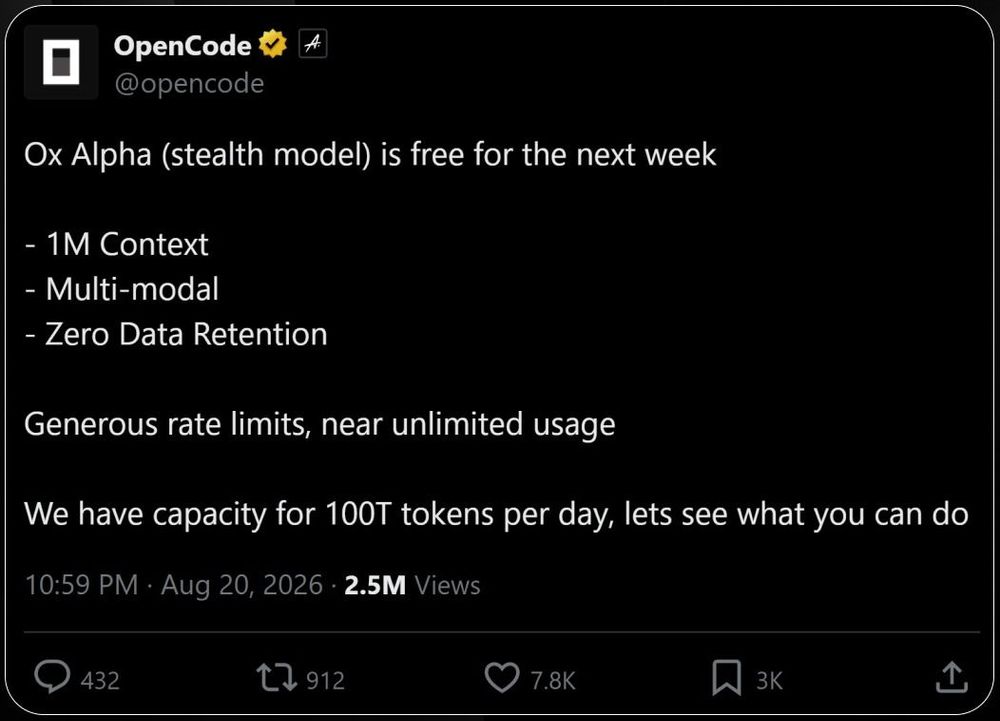
OpenCode's Ox Alpha announcement, cropped to remove unrelated publisher branding. This image documents a social-media claim, not independent verification.
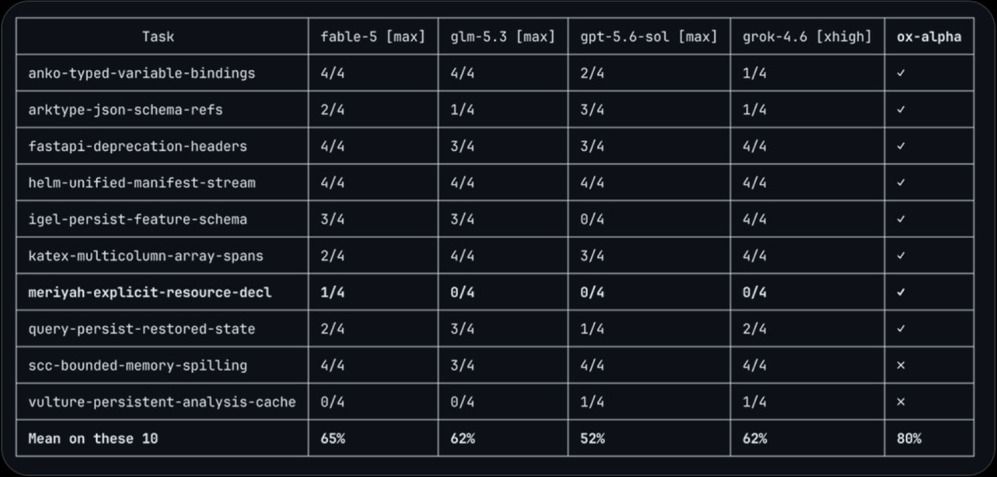
Community-shared DeepSWE subset comparison. The image itself notes that the sample is only ten tasks; it should not be generalized to overall model quality.
For builders, the right takeaway is not “Ox Alpha beats every model.” It is that Z.AI demonstrated a high-attention path from anonymous preview to confirmed GLM release, while the strongest early user signal appeared in coding workflows. Test the exact model, harness, prompt, context, retries, and accepted changes before making a production decision.
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
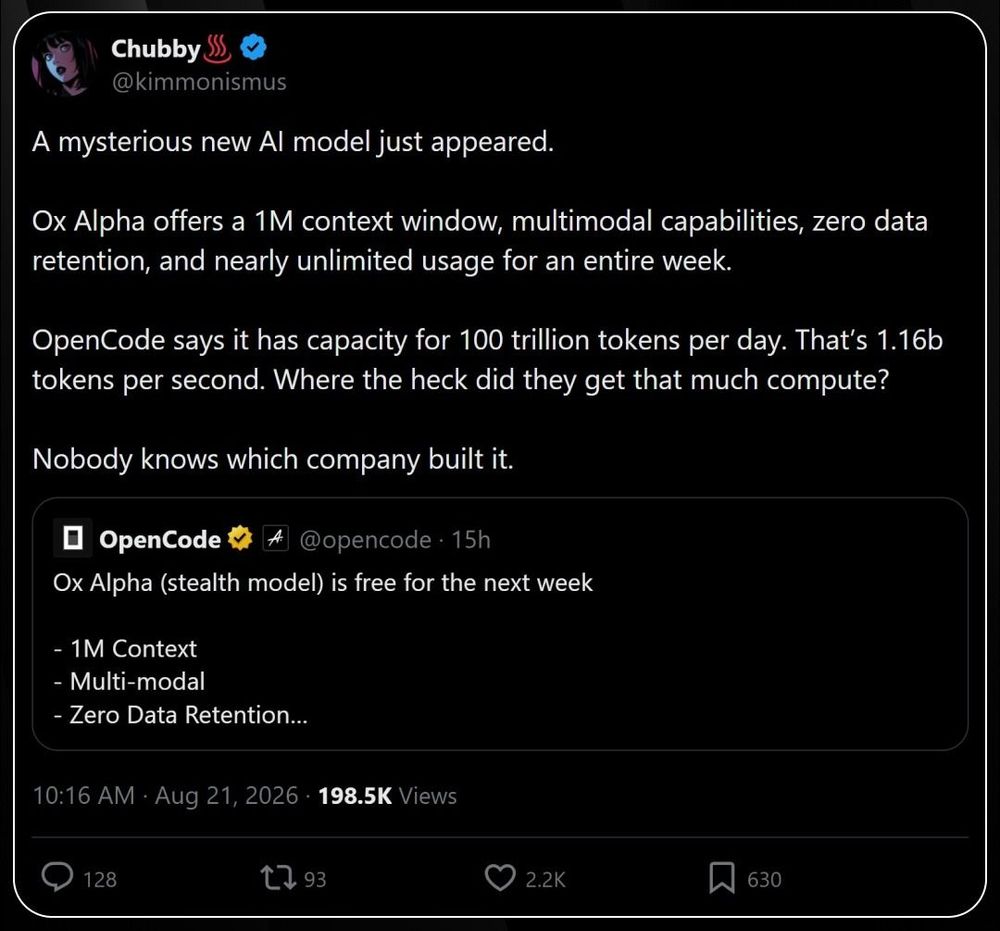
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
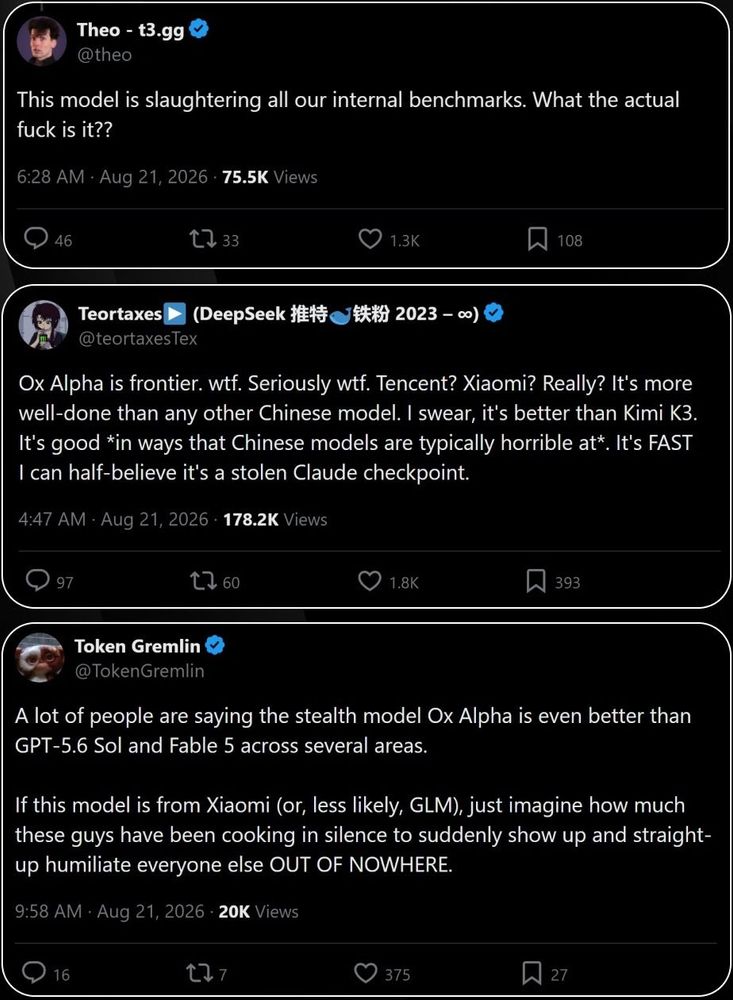
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
 چرا Atoms؟
تیم چندایجنتی هوش مصنوعی
مدیر محصول، مهندس و طراح با هم کار میکنند تا پرامپت شما را به یک محصول کامل تبدیل کنند.
در چند دقیقه منتشر کنید، نه چند ماه
با یک مکالمه، از ایده به محصول دیپلویشده برسید. بدون راهاندازی، بدون پیکربندی.
مالکیت کامل کد
هر زمان به گیتهاب خروجی بگیرید. مالک همهچیز شمایید — بدون وابستگی به فروشنده.
فوراً آنلاین شوید. Atoms میزبانی، SSL و پیکربندی سرور را مدیریت میکند تا شما روی ساخت تمرکز کنید.
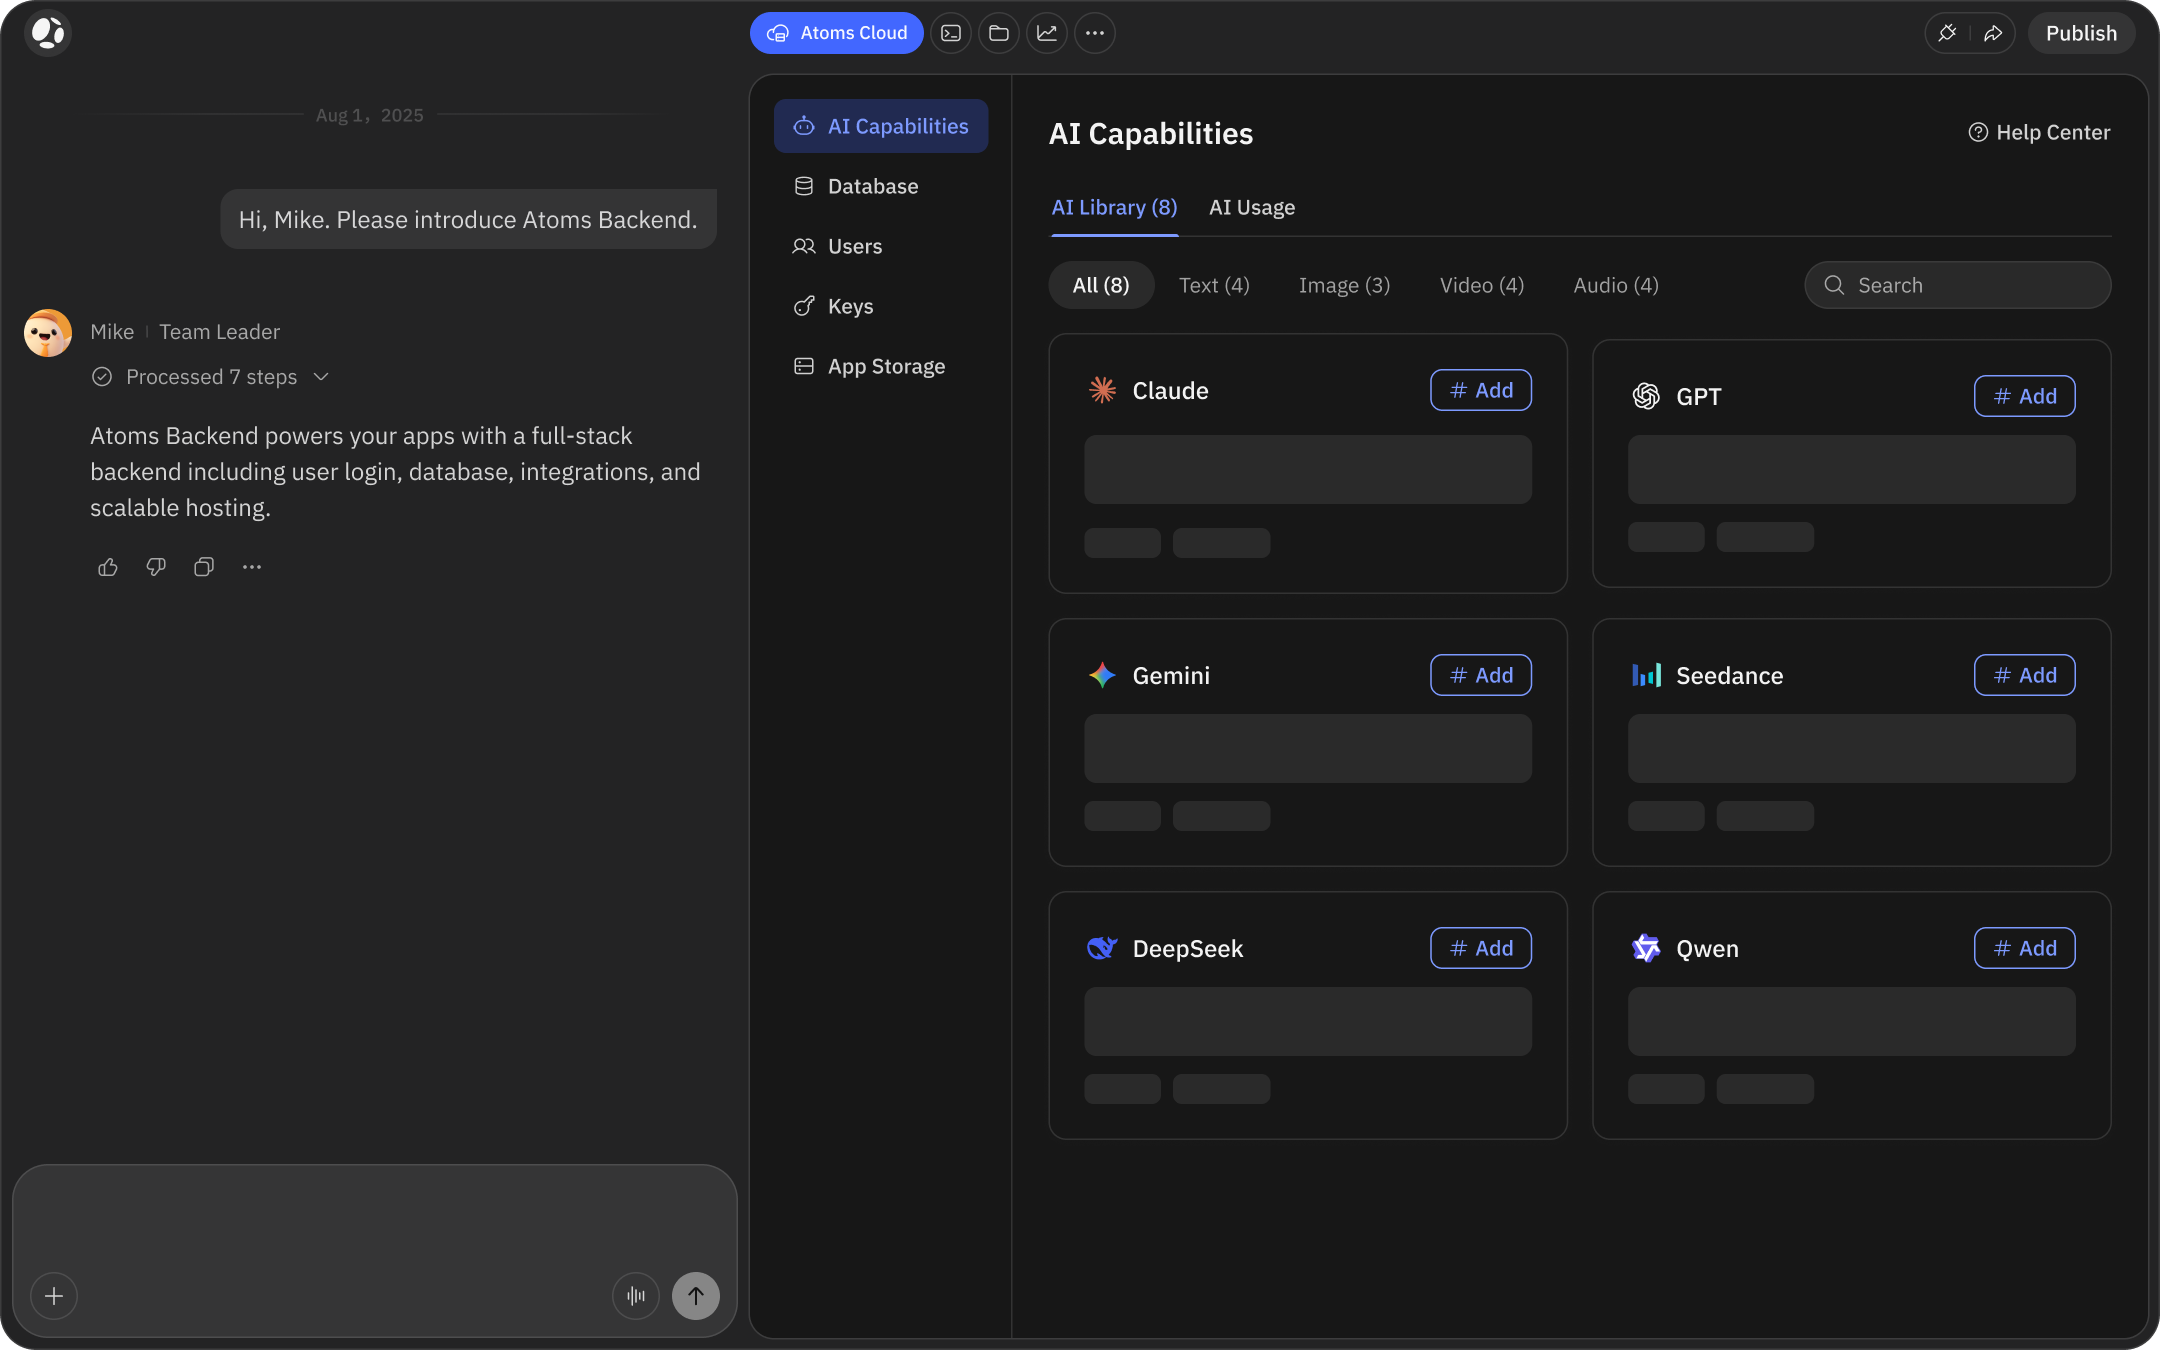
اپلیکیشن خود را بهصورت بصری ویرایش کنید — چیدمانها، رنگها و محتوا را بدون دستکاری کد تنظیم کنید.
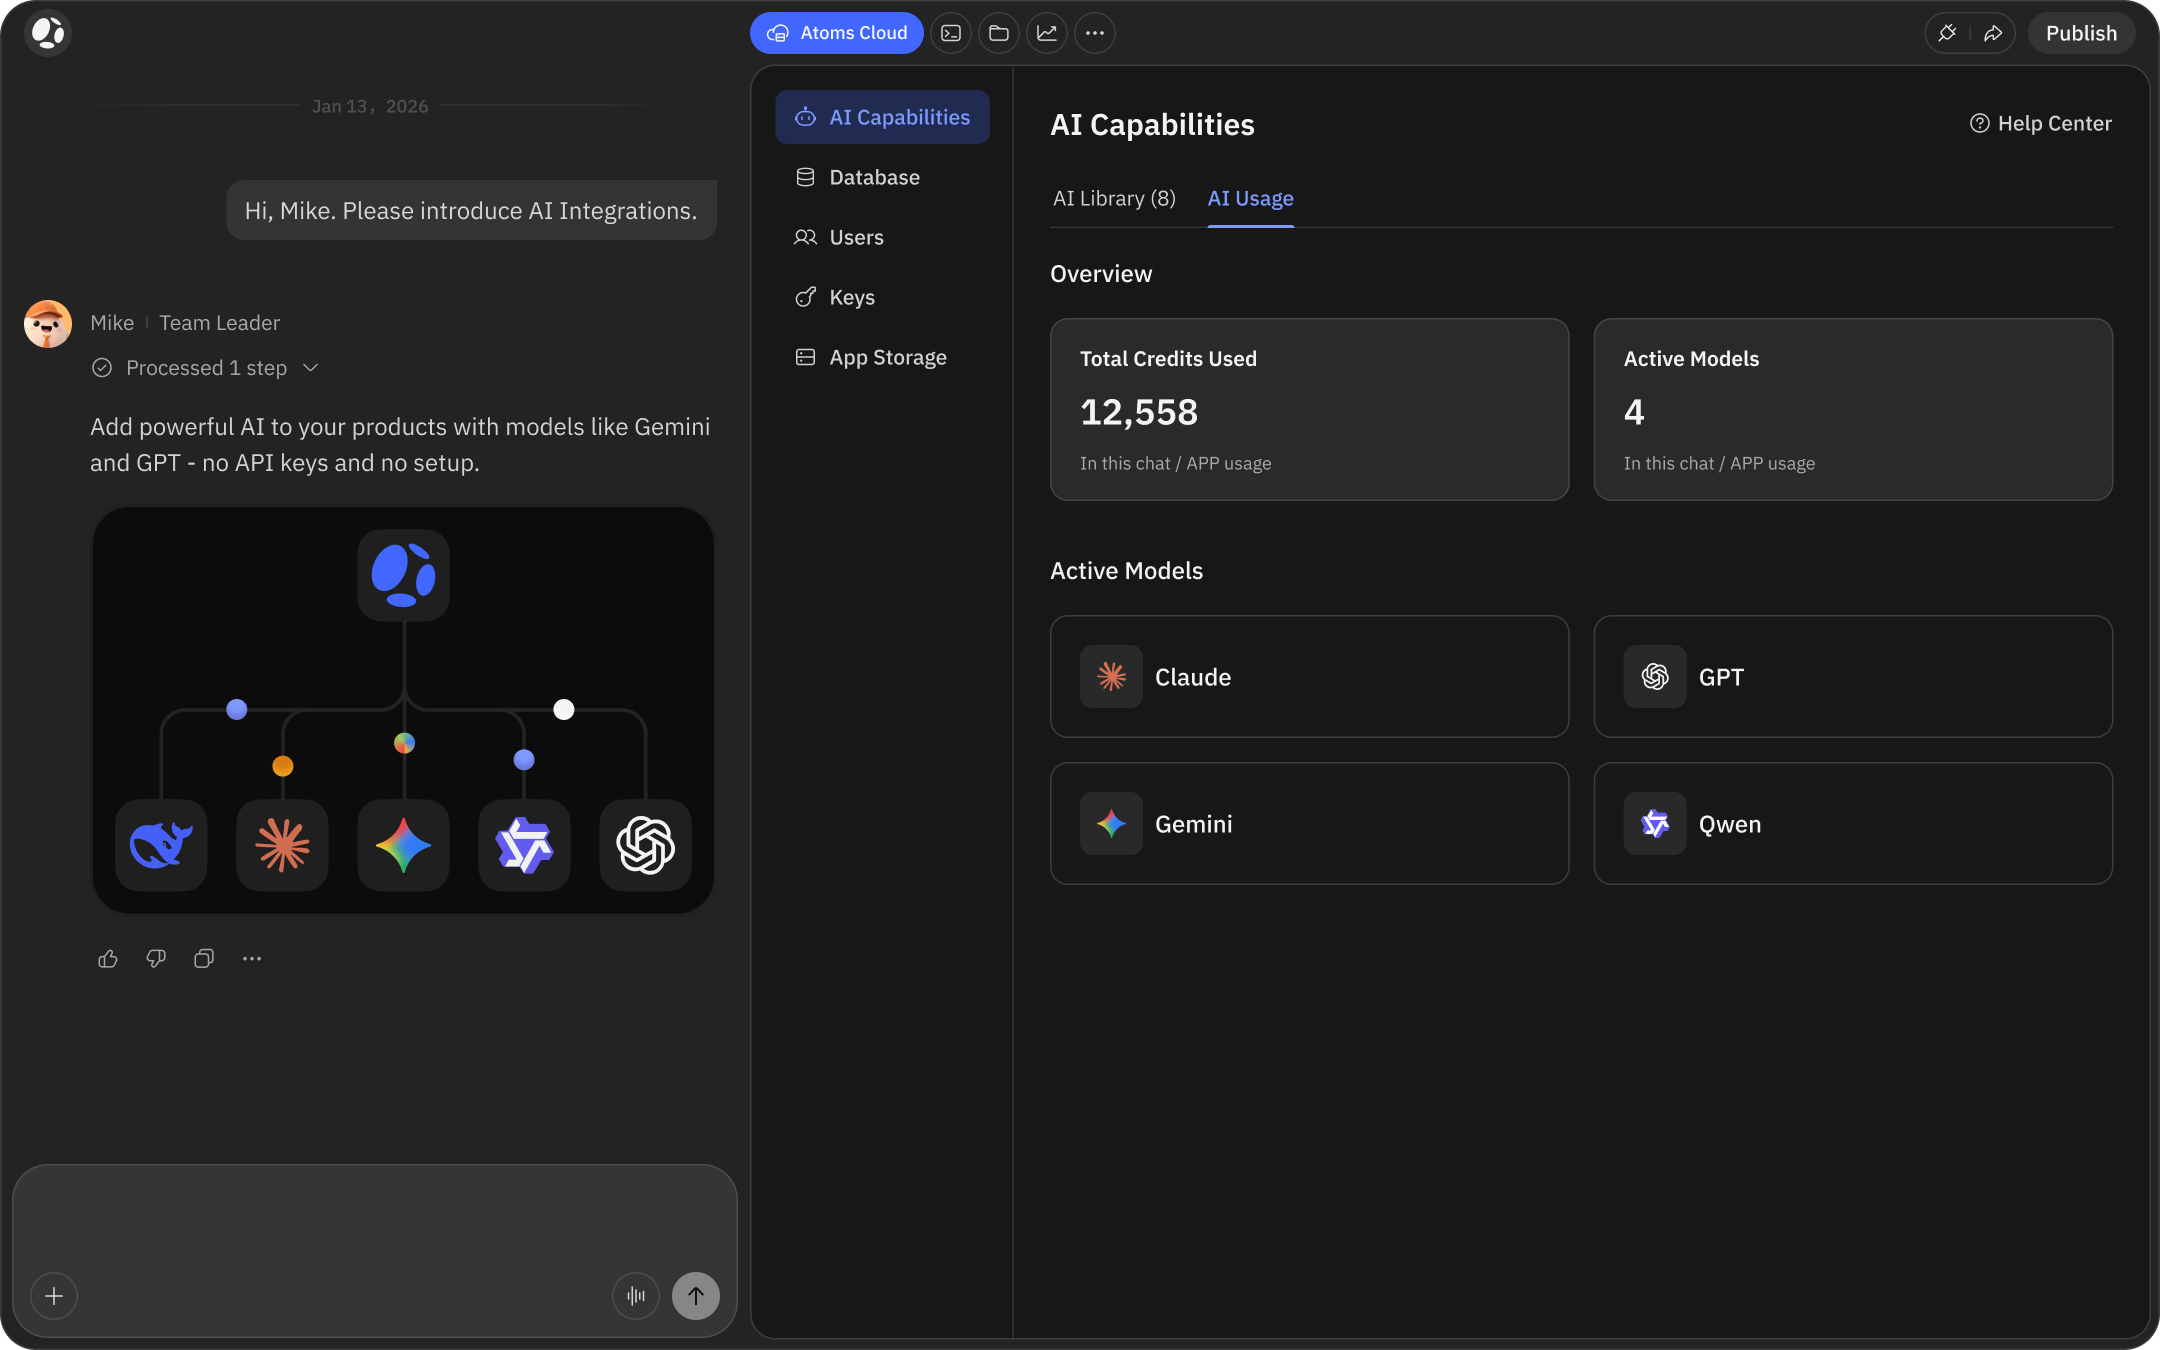
با یک پرامپت، قابلیتهای مبتنی بر هوش مصنوعی — چتباتها، تولید تصویر، تحلیل متن — را اضافه کنید.
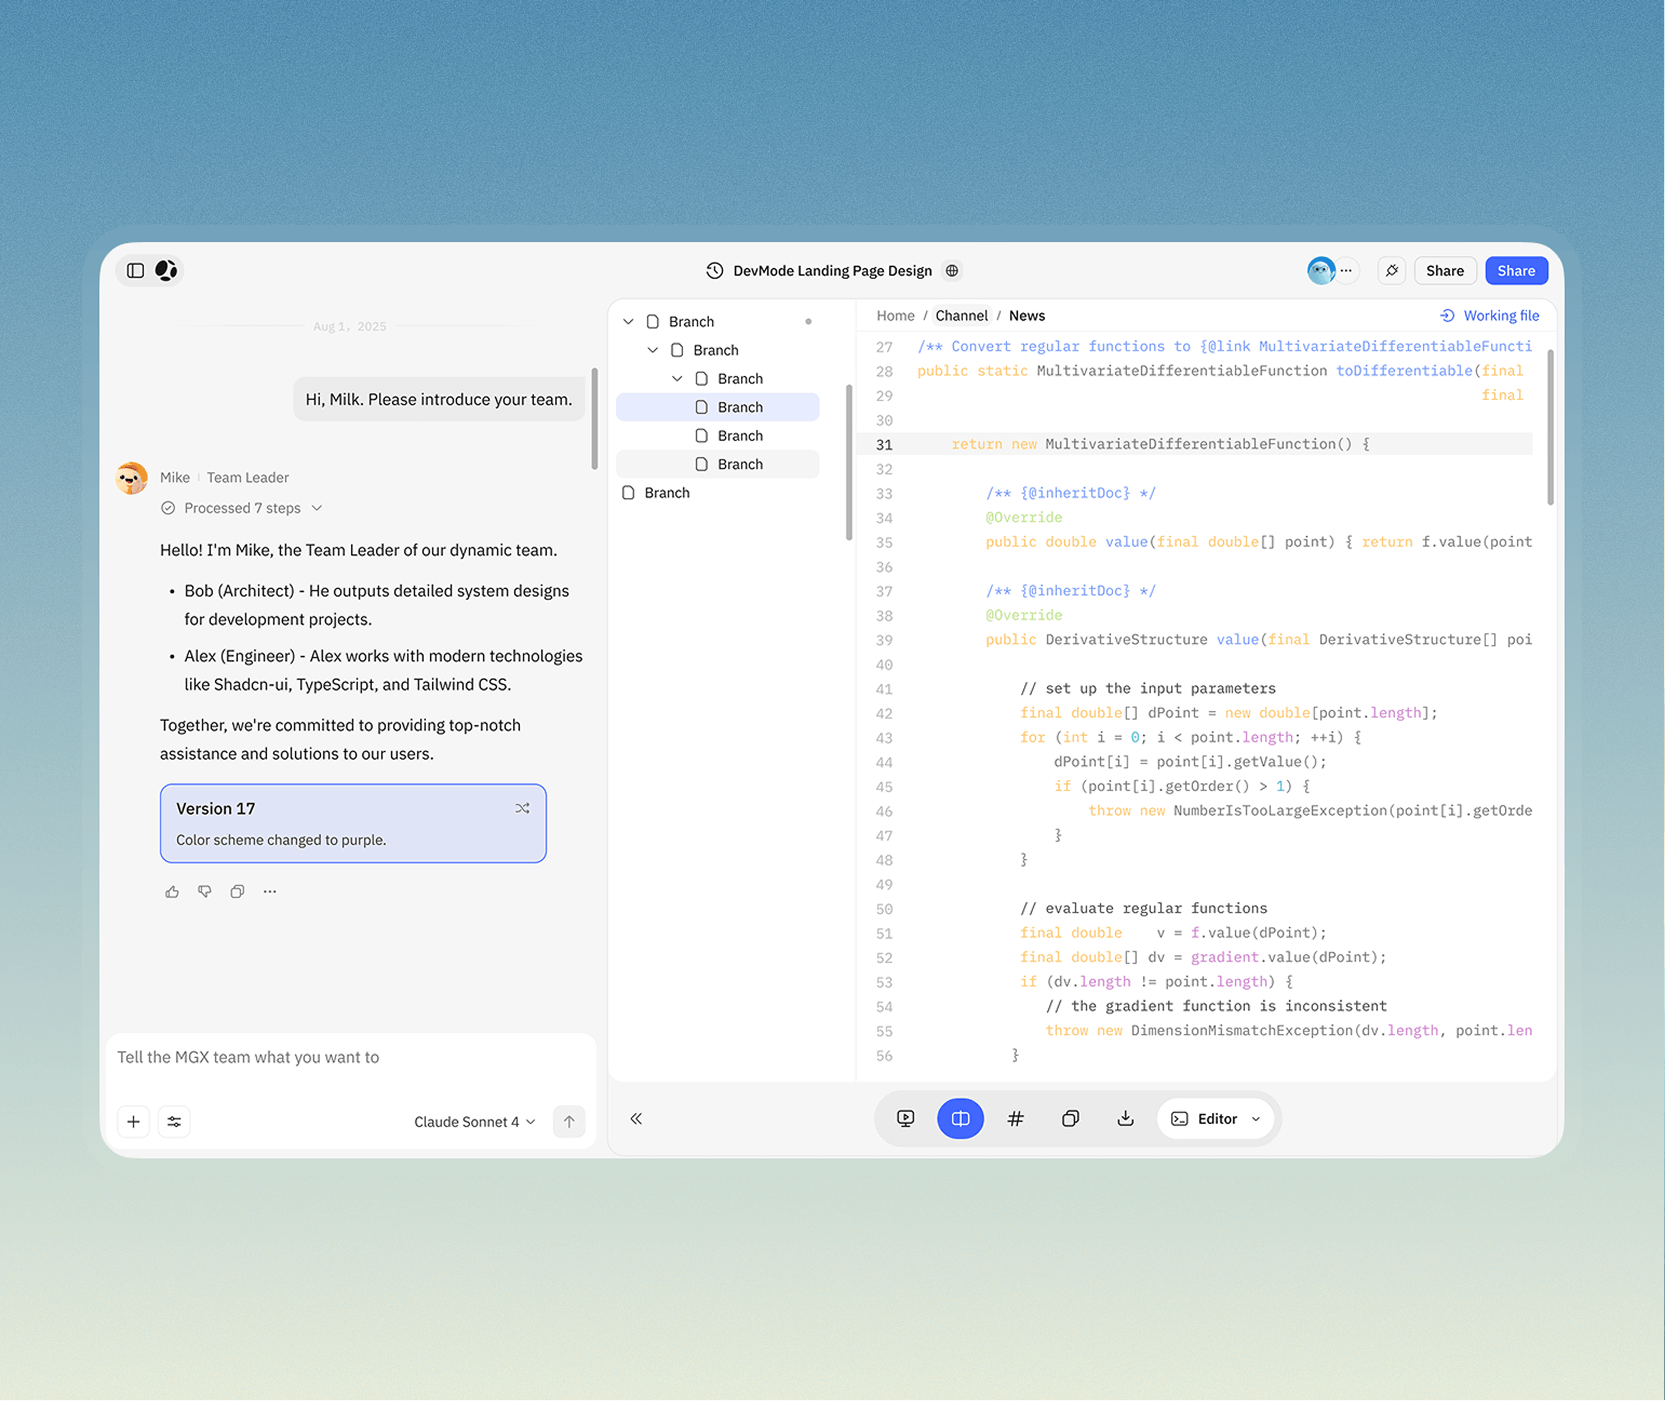
یک تیم کامل هوش مصنوعی — مدیر محصول، مهندس و طراح — با هم همکاری میکنند تا پرامپت شما را به یک محصول قابلاستفاده تبدیل کنند.
داشبورد SaaS
یک SaaS فولاستک با احراز هویت کاربران، مدیریت صورتحساب و تحلیلهای لحظهای بسازید.
فروشگاه تجارت الکترونیک
یک کاتالوگ محصول با سبد خرید، تسویهحساب و پرداختهای Stripe بسازید.
ابزارهای داخلی
پنلهای مدیریت، CRMها و ابزارهای گردش کار تیمتان را در چند دقیقه منتشر کنید.
اپلیکیشن موبایل
اپلیکیشنهای موبایل چندسکویی با رابط کاربری شبیه بومی و اعلانهای پوش بسازید.
Atomsبدون کارت اعتباری. بدون راهاندازی. فقط چیزی را که میخواهید توصیف کنید؛ Atoms آن را میسازد و منتشر میکند.
Turn project-scale coding and long-horizon agent ideas into products you can review, verify, and deploy.
