


Déploiement en un clic
Mettez en ligne instantanément. Atoms gère l’hébergement, le SSL et la configuration du serveur pour que vous puissiez vous concentrer sur la création.
Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context.
Aucune carte de crédit requiseDéployez en quelques secondesPropriété complète du code
Approuvé par des clients de


GLM-5.2 is an AI model available through Atoms for coding, reasoning, research, and tool-driven workflows. Z.ai’s flagship model for project-scale engineering, long-horizon coding, agent workflows, and reliable execution across a 1M-token context. Review the model details below, compare alternatives, and start with the example prompt in the hero.
| Decision point | What to check |
|---|---|
| Best for | coding, reasoning, research, and tool-driven workflows |
| Access | Available through the Atoms model workflow when shown in the current model selector |
| Evidence | Provider information and the practical guidance on this page |
| Limitation | Results depend on the prompt, task, selected settings, and review workflow |
| Page verified | August 23, 2026 |
GLM-5.2 is Z.ai’s flagship foundation model for long-horizon tasks. Z.ai positions it for project-scale engineering contexts where the model must retain architecture, API contracts, repository conventions, and earlier decisions while taking work from requirements to a deployable product. It accepts text input and produces text output.
Z.ai highlights GLM-5.2 for codebase audits, large refactors, API migrations, mobile debugging, Mini Program development, research reproduction, and other workflows where context continuity and reliable follow-through matter.
In August 2026, an anonymous model called Ox Alpha appeared on OpenRouter with a one-week free-access promotion. Developers and Reddit users spent several days trying to identify its provider. Bloomberg later reported that Z.AI confirmed Ox Alpha was a new iteration of its GLM series and planned to release the weights.
The episode matters because it was not only a launch stunt. Early developer reports focused on coding and agent tasks, while the model's identity was investigated through serving behavior, tokenizer and output fingerprints, and error-message similarities. Those community tests are evidence of the investigation—not a substitute for an official model card or a controlled benchmark.
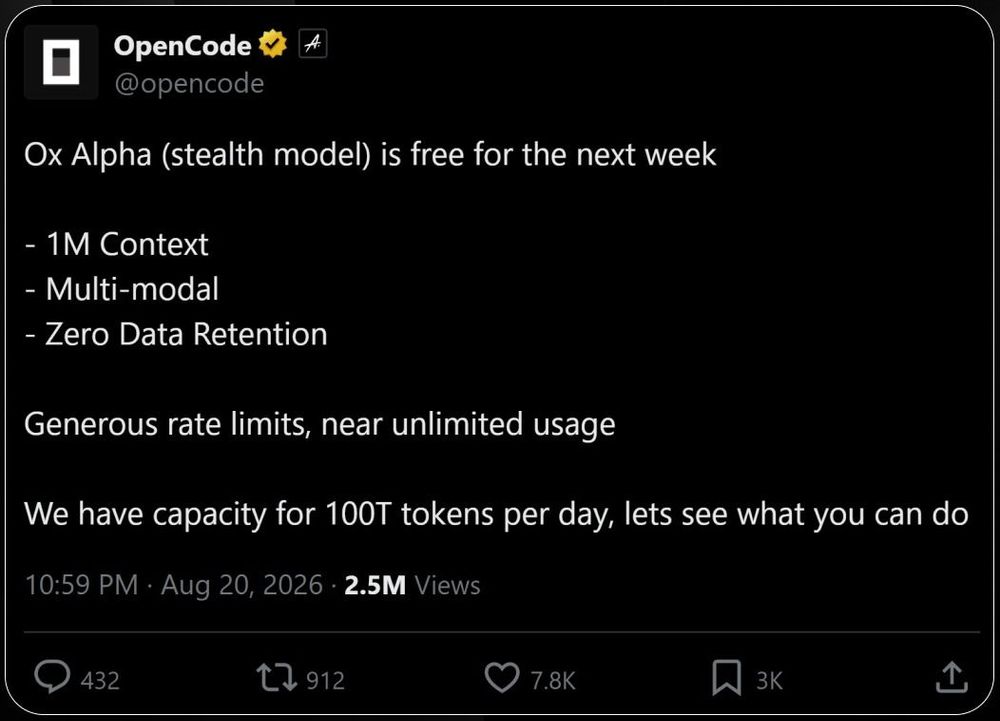
OpenCode's Ox Alpha announcement, cropped to remove unrelated publisher branding. This image documents a social-media claim, not independent verification.
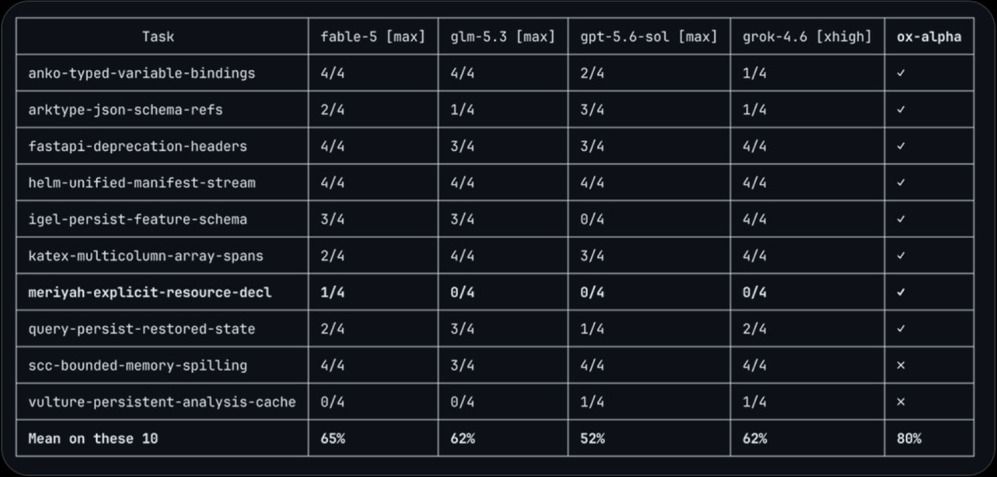
Community-shared DeepSWE subset comparison. The image itself notes that the sample is only ten tasks; it should not be generalized to overall model quality.
For builders, the right takeaway is not “Ox Alpha beats every model.” It is that Z.AI demonstrated a high-attention path from anonymous preview to confirmed GLM release, while the strongest early user signal appeared in coding workflows. Test the exact model, harness, prompt, context, retries, and accepted changes before making a production decision.
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
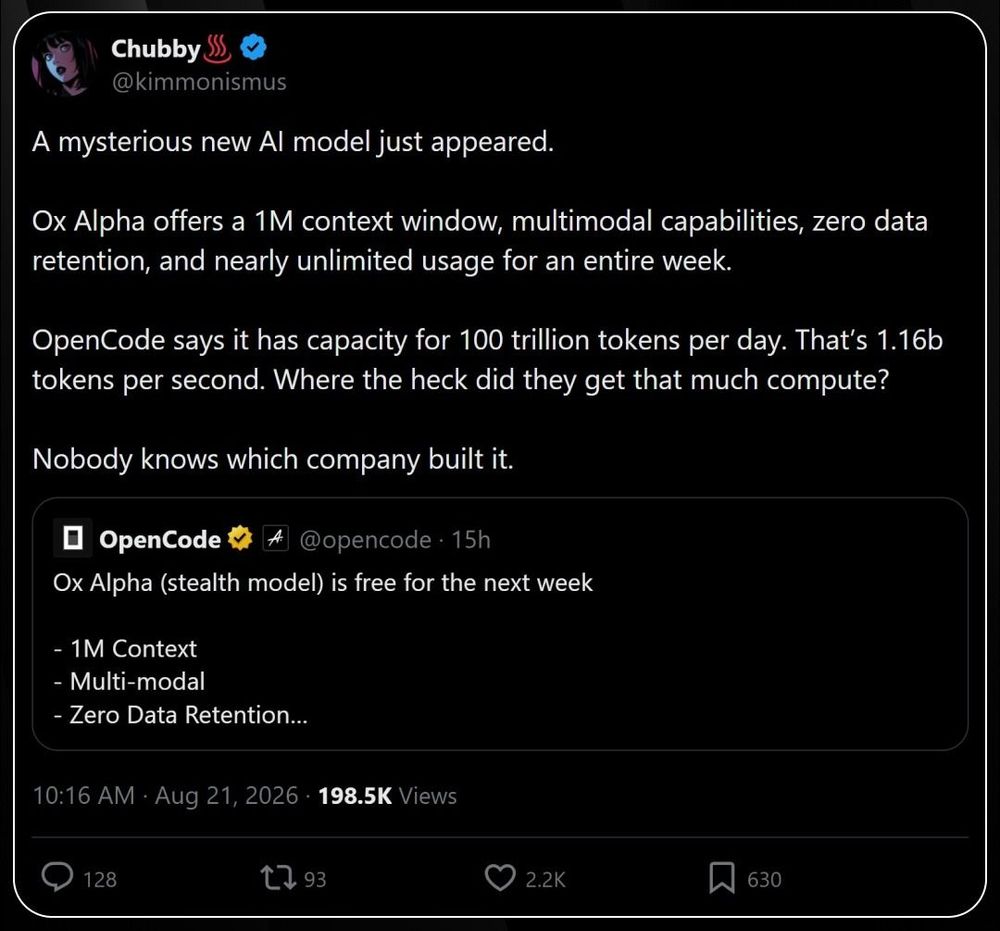
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
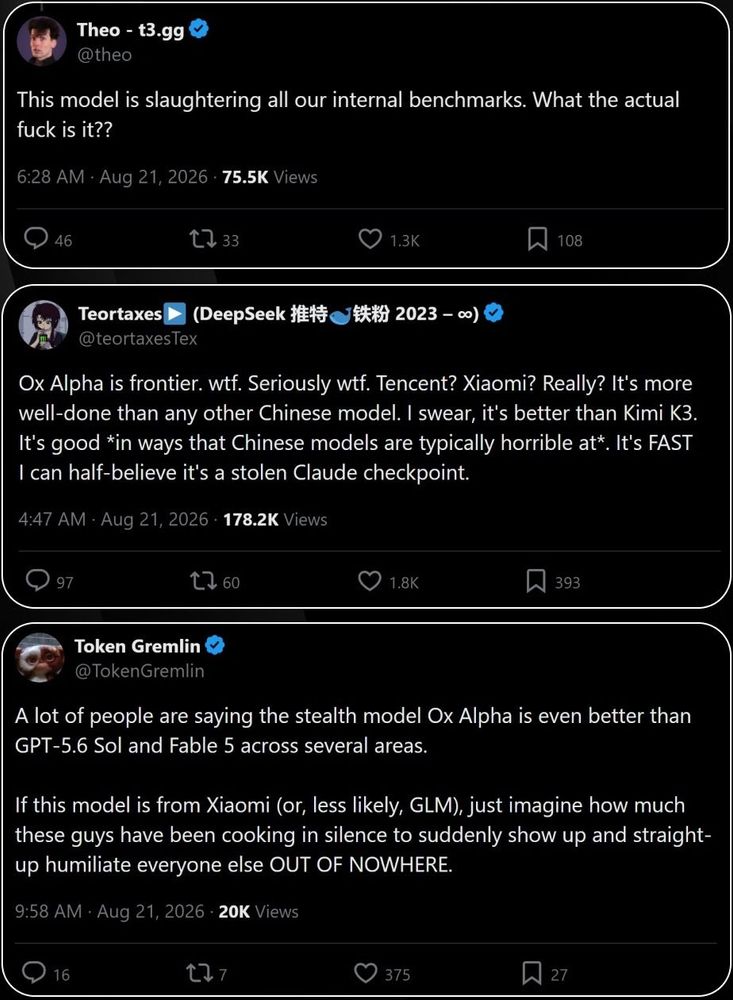
Ox Alpha evidence image, cropped to remove unrelated Evolving AI publisher branding. Treat social posts and community benchmark claims as reported evidence, not independent verification.
 Pourquoi Atoms
Équipe d’IA multi-agents
Le PM, l’ingénieur et le designer travaillent ensemble pour transformer votre prompt en un produit complet.
Lancez en quelques minutes, pas en plusieurs mois
Passez de l’idée au produit déployé en une seule conversation. Sans installation ni configuration.
Propriété complète du code
Exportez vers GitHub à tout moment. Vous possédez tout — sans dépendance fournisseur.
Mettez en ligne instantanément. Atoms gère l’hébergement, le SSL et la configuration du serveur pour que vous puissiez vous concentrer sur la création.

Modifiez votre application visuellement — ajustez les mises en page, les couleurs et le contenu sans toucher au code.

Ajoutez des fonctionnalités alimentées par l’IA — chatbots, génération d’images, analyse de texte — avec un seul prompt.

Une équipe IA complète — PM, ingénieur, designer — collabore pour transformer votre prompt en produit fonctionnel.
Tableau de bord SaaS
Créez une solution SaaS full-stack avec authentification utilisateur, facturation et analyses en temps réel.
Boutique e-commerce
Créez un catalogue de produits avec panier, paiement et paiements Stripe.
Outils internes
Déployez des panneaux d’administration, des CRM et des outils de workflow pour votre équipe en quelques minutes.
Application mobile
Créez des applications mobiles multiplateformes avec une interface au rendu natif et des notifications push.
De vraies applications et pages que des équipes ont mises en ligne sur Atoms — choisissez-en une comme point de départ.
Décrivez votre cabinet et obtenez un site déployé avec domaines de pratique, profils d’avocats et prise de rendez-vous pour consultation.
Obtenez un site d’agence déployé avec pages portfolio, études de cas, profils d’équipe et capture de leads.
Transformez des idées de produits brutes en prototypes interactifs que vous pouvez cliquer, partager et tester en quelques minutes.
Décrivez le produit que vous souhaitez, Atoms construit l'application et le site Web pour vous.
Mettez en valeur votre travail sur un site portfolio en ligne avec pages projet, galeries, témoignages et formulaires de contact.
Créez un site Web personnalisé à partir d'une description textuelle — les agents IA s'occupent du design, du code, du backend et du déploiement.
AtomsPas de carte bancaire. Pas de configuration. Décrivez simplement ce que vous voulez, et Atoms le livre.
Turn project-scale coding and long-horizon agent ideas into products you can review, verify, and deploy.
